
2× NVIDIA DGX Spark cluster 256GB Configuration to run a model across two devices · Total memory 256GB
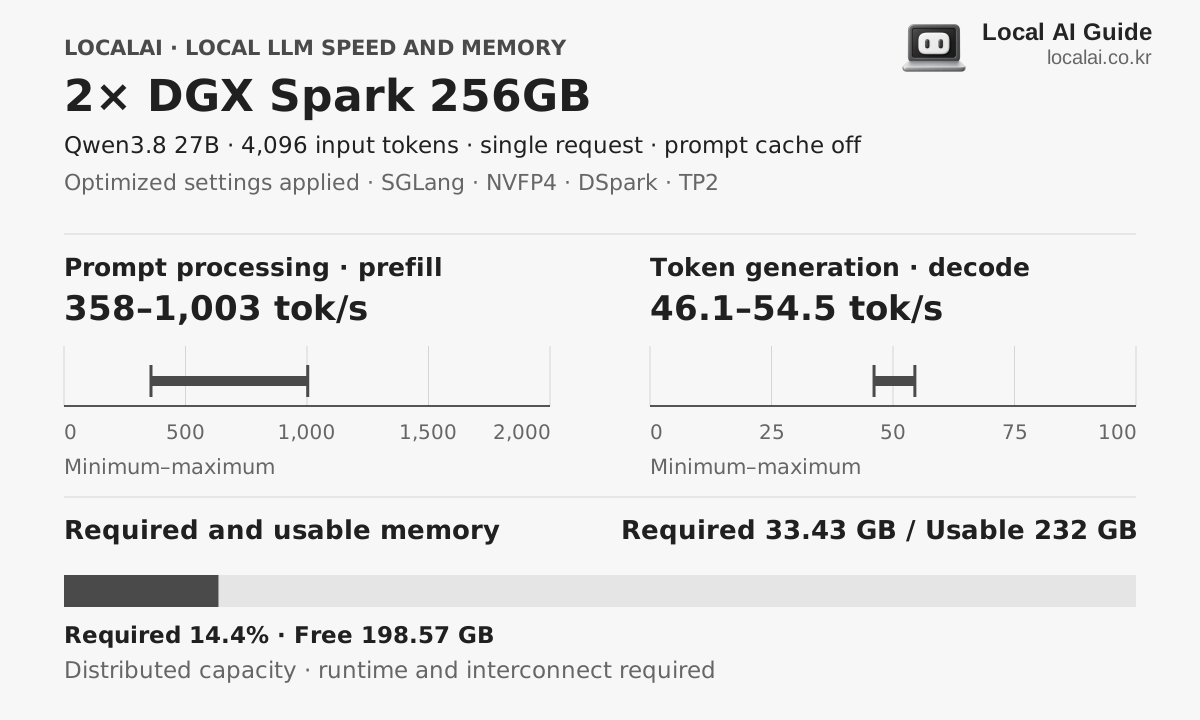
Two nodes connected by a ConnectX-7 200 Gbps (25 GB/s) RoCE link (256 GB total distributed memory, 546 GB/s combined local bandwidth). When optimizing TP=2, even a single request can be faster, and the measured configuration for each model is applied first.
Speed and memory for the same model
Hardware core specifications
- Available memory
- 232GB
- Memory bandwidth
- 546GB/s
- Estimated sustained LLM load
- About 380W
- Korean price range (KRW)
- 1,904 × KRW 10,000–2,060 × KRW 10,000
Who it fits
- Utilize 232GB of available memory
- Two-Device Distributed Inference
- GLM-5.3-Flash (MoE) model comparison
Skip it if
Even if you connect two devices, the memories are not automatically merged into one. Distributed runtime support and interconnect bottlenecks must be checked together.
Recommended format for each device 4K input
The model you will experience with this equipment
K2 Horizon 0.9B
Required 1.03GB · spare time
4-bit · 2-node setup
Decode
370.9 ~ 593.4 tok/s
First token
0.24 to 0.62 seconds
GLM-5.3-Flash (MoE)
recommendedRequired 190.21GB · titration
4-bit · 2-node setup
Decode
18.5 ~ 29.6 tok/s
First token
4.8 to 12.3 seconds
Actual speed varies with runtime version, cooling, context length and quantization file.
On sales pages, look at memory before chips.
The model and speed assumptions above change if the product is not the 256GB configuration.
Frequently asked questions
- What LLM can be run on 2× DGX Spark 256GB?
- K2 Horizon 0.9B, GLM-5.3-Flash (MoE) and others with a 4K input and the recommended format. Required memory varies by model and context length.
- How much local LLM computing power does 2× DGX Spark with 256GB provide?
- Sustained load is about 380 W, with an actual range of 320–466 W.
- Are the displayed token speeds ground truth?
- This is a range aligned to collected benchmark measurements under the same conditions. Combinations without a matching measurement are estimated from the nearest result and vary with runtime, cooling, quantization file and context length.
Equipment to compare together
similar memory
Studio M5 Ultra 256GB
In a public measurement using Flash-Next 4-bit with MTP, a 4K input was processed at about 2,600–2,900 tok/s and a 512-token answer landed in the 90–112 tok/s range. Prefill held near 2,500 tok/s even at a 256K input. Beyond the larger unified memory, the shorter wait for a first answer on long prompts is the biggest difference from M3 Ultra.
similar memory
Studio M4 Max 128GB
Suits people who want to compare a wide range from 70B-class to high-precision models in a single finished machine.
similar memory
Ryzen AI Max+ 395 128GB
It is attractive when you have large amounts of integrated memory at a low price and can handle runtime settings directly.