
RTX 3090 24GB Before checking the used price, check whether your PC can take a 24GB GPU.
If you own an RTX 3090, first check whether the target model and context fit in 24GB. Newer hardware alone is not a reason to replace a card that completes your work. For a used purchase, include power, cooling, case compatibility and return terms in the cost.
Speed and memory for the same model
Hardware core specifications
- Available memory
- 22.5GB
- Memory bandwidth
- 936GB/s
- Estimated sustained LLM load
- About 420W
- Korean price range (KRW)
- 239 × KRW 10,000–239 × KRW 10,000
Who it fits
- Add 24GB VRAM to an existing PC
- Q4 workloads that fit in 24GB
- ComfyUI image generation
Skip it if
Avoid a used card if you cannot check its condition under load or the return terms if something goes wrong. Seeing it display an image once is not enough. Before buying, also check whether that manufacturer's model fits your PC in length, thickness, and power connections.
Recommended format for each device 4K input
The model you will experience with this equipment
K2 Horizon 0.9B
Required 1.03GB · spare time
llama.cpp CUDA · Q4_K_M
Decode
1271.5 ~ 1412.8 tok/s
First token
0.26 to 0.45 seconds
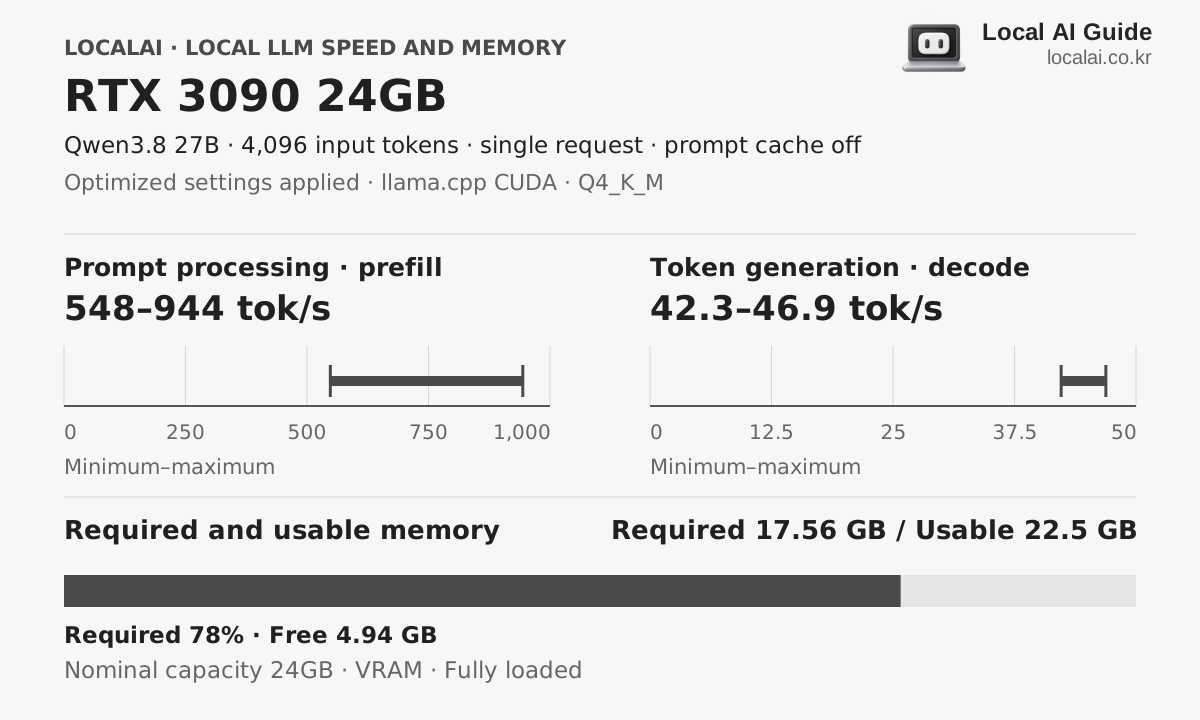
Qwen3.8 27B
recommendedRequired 17.56GB · titration
llama.cpp CUDA · Q4_K_M
Decode
42.3 ~ 46.9 tok/s
First token
4.4 to 7.5 seconds
Qwen3.8-Flash-Next
Required 60.0561152GB · tight
Strata 0.1.34 · IQ2_XS · MTP · INT8 KV · pcie-frac 0 · SSD PLE
Decode
74.9 ~ 135.1 tok/s
First token
8.1 to 14.6 seconds
Actual speed varies with runtime version, cooling, context length and quantization file.
purchase judgment
What tasks is it suitable for?
27B conversation
SuitableCount both the 27B Q4 file and the input cache. Do not mix the speed of a fully GPU-resident configuration with one that offloads part of the model to RAM.
Create image
SuitableIn ComfyUI, check whether the model, resolution and batch size fit within 24GB. Low-precision kernels built for newer GPUs do not necessarily work the same way on a 3090.
24 hour server
ConditionalSeparate time powered on from time spent generating. The card does not draw its rated power all day, but sustained generation still means dealing with cooling and noise.
- The first thing to get stuck
- A 70B model's raw 4-bit weights alone are roughly 35GB before metadata and context cache. Do not compare an offloaded run as though it were fully resident on one 24GB card. RAM offloading may enable execution without preserving fully resident speed.
- Configuration to check
- RTX 3090 24GB card only · 64GB system RAM in this comparison · Check PSU, case fit, and warranty for the manufacturer's model
- Criteria for spending more money
- A 24GB RTX 4090 may improve speed but does not automatically solve a capacity problem. Before moving to 32GB, check that the target workload fits there. Tasks that fit 16GB can also be compared with smaller new configurations, including power, warranty and full-system cost.
On sales pages, look at memory before chips.
The model and speed assumptions above change if the product is not the 24GB configuration.
Frequently asked questions
- What LLM can be run on a local LLM using an RTX 3090 24GB?
- K2 Horizon 0.9B, Qwen3.8 27B, Qwen3.8-Flash-Next and others with a 4K input and the recommended format. Required memory varies by model and context length.
- What is the power consumption of a local LLM on an RTX 3090 24GB?
- Sustained load is about 420 W, with an actual range of 330–540 W.
- Are the displayed token speeds ground truth?
- This is a range aligned to collected benchmark measurements under the same conditions. Combinations without a matching measurement are estimated from the nearest result and vary with runtime, cooling, quantization file and context length.
Equipment to compare together
Workloads that only need 16GB
RTX 5060 Ti 16GB
448 GB/s GDDR7 VRAM. 16GB entry desktop GPU with 8B and 12B Q4 models 100% loadable in dedicated VRAM.
Compare speed at the same 24GB capacity
RTX 4090 24GB
This is the machine to look at if you want to quickly process LLM and image creation that fit in 24GB and avoid the new high price.
When 24GB runs out of memory
RTX 5090 32GB
Compare this card if you repeatedly generate images or run 27B–35B inference and want shorter waits. But 32GB is still a limit. Buying on compute performance alone, without checking the model, input and image resolution, may leave you offloading again.