
read first
Last updated
China's AI Export Controls: What Happens to the Models You Use on OpenRouter?
Understand changes to hosted access and prepare a local option.
China has proposed additional controls on transferring certain AI technologies overseas. As of October 17, 2026, pre-export registration has begun for covered transfers, while the final scope remains under consultation. Receiving an answer through an API1 and deploying a model on an overseas server receive different treatment. Start with how you access the model to decide what to keep using and what to prepare.
What has started and what is still being decided
On October 16, 2026, China's commerce and science ministries proposed adding AI, biotechnology, and solar technologies to its catalog of prohibited or restricted technology exports. The AI categories cover large models, agents, computing clusters, and information processing. The controls focus on which technology is transferred overseas and how that transfer happens.
The consultation runs through November 15. Until the revised catalog formally takes effect, exporters must register covered technology transfers in advance. Keep the registration already underway separate from the final rules still being consulted on. For a model you use now, its delivery method and the service's own notices are the practical points to check.
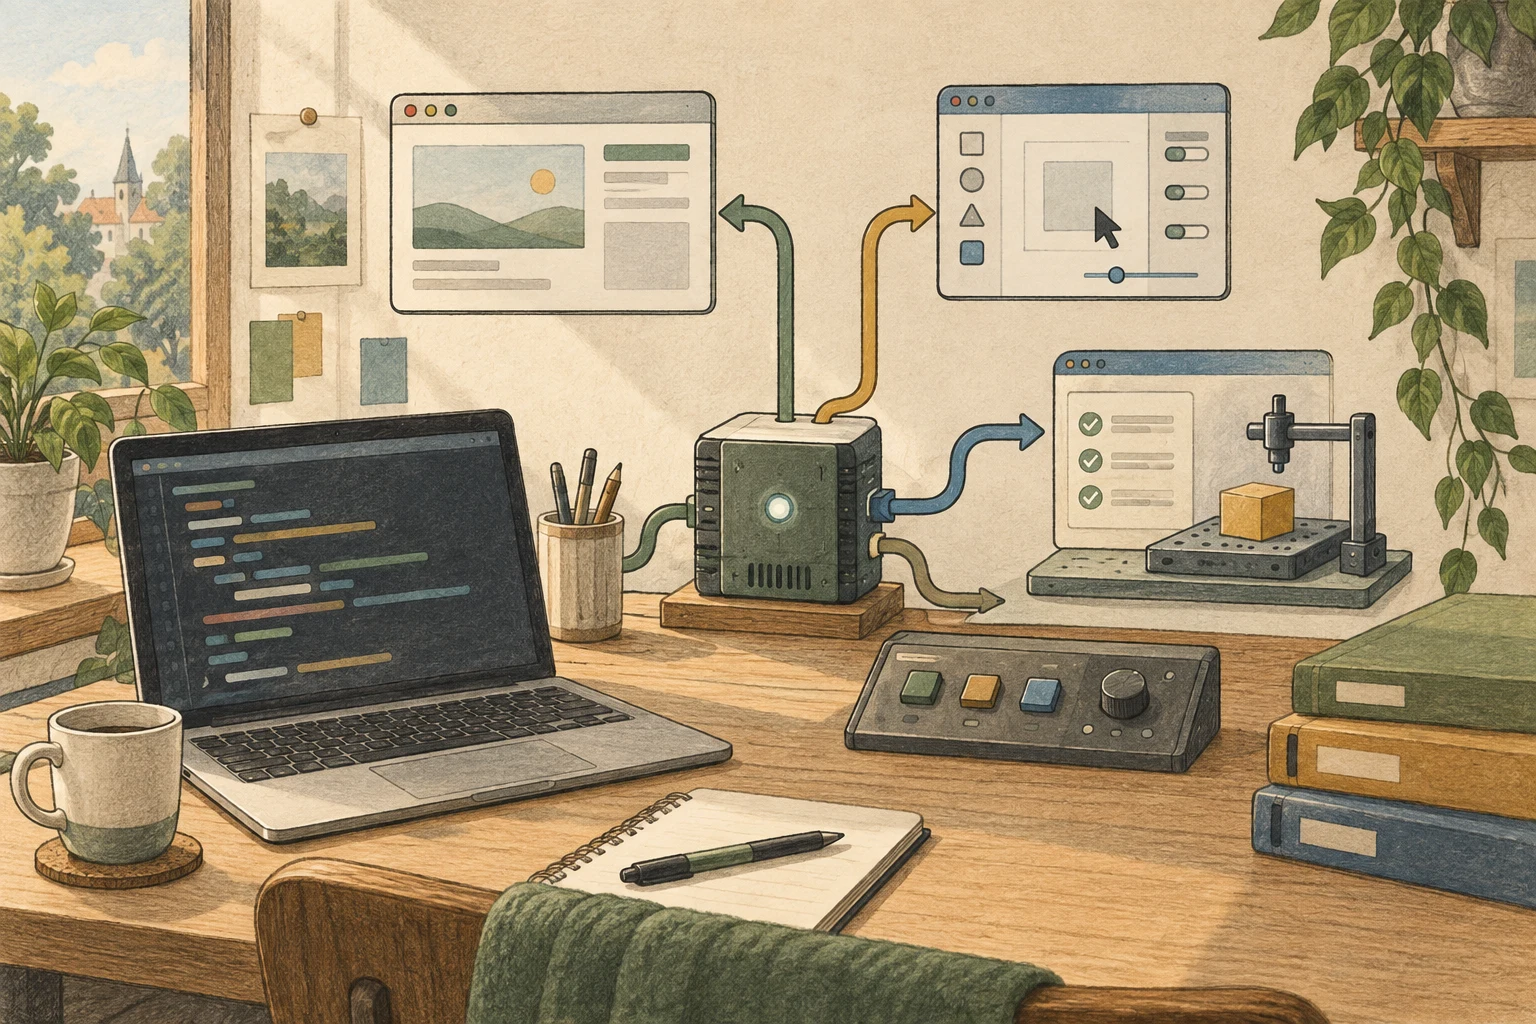
Receiving an API answer versus transferring a model overseas
When you send a question to OpenRouter, a connected provider runs the model on its servers and returns an answer. If an overseas operator receives the model files and installs them on its own servers, the model technology itself is transferred. The official Q&A treats these cases differently.
| Access or delivery method | Treatment in this announcement |
|---|---|
| Using a company's API, app, website, or SaaS | Described as outside large-model technology export management |
| Deploying restricted AI technology on overseas servers | Subject to technology export management, with facilitation for cases such as an overseas self-operated cloud |
| Technology already public through open source, papers, or similar channels | Explicitly excluded from the management scope |
| Lightweight deployment on local end devices | Listed in the Q&A as outside large-model technology export management |
Based on the Chinese Ministry of Commerce announcement and Q&A dated October 16, 2026.
What could change on OpenRouter?
OpenRouter lets you use multiple providers' inference2 APIs through one connection. A model may have several providers with different speeds, prices, and data-processing locations. Even when you select the same model on OpenRouter, different providers' servers may handle your requests.
A provider acquiring restricted technology to operate it on overseas servers may be affected by technology-transfer procedures. Current preregistration and the management rules still to be finalized could affect when an overseas provider adds a new endpoint. This is a scenario based on the distinction between connecting an existing API and newly hosting a model overseas.
This announcement contains no decision to stop model availability on OpenRouter or block all Qwen or DeepSeek use. If a model you use changes, check its model page for the provider and available regions, then read that provider's notice to identify affected endpoints.
What a local LLM lets you keep doing
A local LLM3 runs downloaded model files on your PC or Mac. For a task such as finding a bug in public code and suggesting a fix, you can send the same code to a local application. Your computer performs the inference, letting you continue that task without relying on a hosted inference API's availability or pricing policy.
Once the model, application, and required runtime4 are downloaded, LM Studio can chat and run a local server without internet access. Finding and downloading additional models requires connectivity. Tasks that use web search or external tools also need those connections, so a self-contained job such as reviewing a code snippet is a straightforward starting point.
Keeping a model locally preserves access to that version's capabilities. If you also need future larger models or a hosted service's search features, divide tasks between the existing API and your local model. Keep the license and usage terms with the downloaded files.
What to prepare before buying another GPU
Start with the hardware finder, selecting your current PC or Mac and a model to narrow down feasible configurations. Leave room for the model files plus the input and conversation state. If your usual work is short exchanges, you can begin with a smaller local model rather than matching the size of the hosted model.
Load the model in your app and enter a piece of code that is safe to share. Ask for the cause of an error and a proposed fix, then follow up about the same function. If you can complete the review and follow-up at a pace that suits your work, keep that setup as a fallback. Separately record whether the answer covers the needed cause and fix, and how long you waited for the first response, to identify reasons for changing models or hardware.
To keep using your existing app, follow the guide to switching from OpenRouter to a local LLM. Preserve a working configuration with the model backup and restore guide. The goal is to have a task you can continue if a service changes, rather than to buy new hardware first.
What to check when something changes next
Watch the final Chinese announcement for the settled scope and exceptions, and your provider's notices for changes to models, regions, or delivery methods. If a model's provider changes, check the data-processing location and privacy terms as well as price. Adjust the connection for the affected task when there is a concrete change.
If your current API works well, keep using it. If a change in provider or terms makes it hard to continue your task, you can switch to the local setup you tested earlier.
Terminology notes
API — A defined interface that lets other code call a program’s functions.
Back to the textInference — The process of using a trained model to compute an output for an input. Here, local inference means running the model on the user’s device.
Back to the textLarge language model — A model trained on large text datasets to learn language patterns and process or generate text in context.
Back to the textRuntime — The software environment that provides facilities needed while a program runs. In local AI, it can also refer to a model execution engine.
Back to the text
Frequently asked questions
- What should you check first in this article?
- China has proposed additional controls on transferring certain AI technologies overseas. As of October 17, 2026, pre-export registration has begun for covered transfers, while the final scope remains under consultation. Receiving an answer through an API and deploying a model on an overseas server receive different treatment. Start with how you access the model to decide what to keep using and what to prepare.
- How much memory does it need?
- Start with the [hardware finder](/?tab=finder), selecting your current PC or Mac and a model to narrow down feasible configurations. Leave room for the model files plus the input and conversation state. If your usual work is short exchanges, you can begin with a smaller local model rather than matching the size of the hosted model.
- Where can you check the conditions and sources?
- Keeping a model locally preserves access to that version's capabilities. If you also need future larger models or a hosted service's search features, divide tasks between the existing API and your local model. Keep the license and usage terms with the downloaded files.