
Mac mini M4 32GB More room than 24GB does not automatically mean faster answers.
Consider this configuration if you want to run 27B Q4 without building a new PC. Moving up makes sense if 24GB was running out of memory. If the model and cache already fit, however, choosing 32GB does not make the chip itself faster.
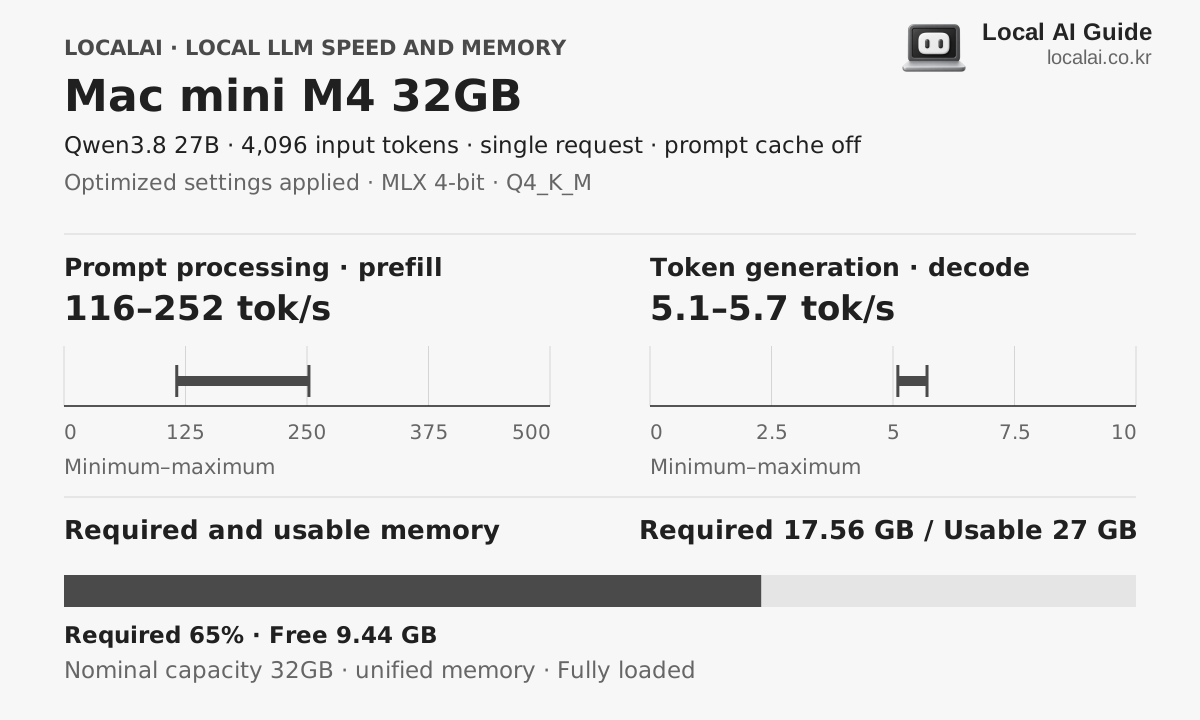
Speed and memory for the same model
Hardware core specifications
- Available memory
- 27GB
- Memory bandwidth
- 120GB/s
- Estimated sustained LLM load
- About 48W
- Korean price range (KRW)
- 180 × KRW 10,000–240 × KRW 10,000
Who it fits
- Run 27B Q4 on one machine
- A personal server without PC assembly
- When 24GB runs out of memory
Skip it if
Do not choose this configuration if you need to move CUDA-only extensions over unchanged. Having 32GB of memory does not make them compatible with macOS. On the product listing, also check the M4 chip, 32GB unified memory, and SSD option separately.
Recommended format for each device 4K input
The model you will experience with this equipment
K2 Horizon 0.9B
Required 1.03GB · spare time
MLX 4-bit
Decode
154 ~ 172.1 tok/s
First token
1.5 to 3.8 seconds
Qwen3.8 27B
recommendedRequired 17.56GB · spare time
MLX 4-bit
Decode
5.1 ~ 5.7 tok/s
First token
16.4 ~ 35.5 s
K2 Horizon MoVA 36B-A4B
Required 21.94GB · titration
MLX 4-bit
Decode
34.6 ~ 38.6 tok/s
First token
9.1 to 24.6 seconds
Actual speed varies with runtime version, cooling, context length and quantization file.
purchase judgment
What tasks is it suitable for?
27B conversation
SuitableCheck a Q4 configuration with 4K input first. Whether a model fits and whether you are comfortable waiting for a long answer are separate decisions.
personal documents
SuitableIf you ask about the same document repeatedly, also look at settings that reuse the cache. More memory alone does not solve document-reading time.
Create image
ConditionalFirst check that your models and nodes support Metal or MLX. If you are moving a CUDA-only workflow, you may need different hardware.
- The first thing to get stuck
- Generation-speed differences add up more over long answers than short ones. Apart from checking whether 27B Q4 fits, try an answer length you would actually be willing to wait for. Longer context also leaves less free memory.
- Configuration to check
- M4 · 10-core GPU · 32GB unified memory · 512GB SSD recommended
- Criteria for spending more money
- If you only use 12B models and have memory to spare in 24GB, you do not need to move to 32GB. If you like the answers from 27B but not the wait, compare prefill and generation times with the M4 Pro 48GB rather than buying a larger SSD.
On sales pages, look at memory before chips.
The model and speed assumptions above change if the product is not the 32GB configuration.
Frequently asked questions
- What LLM can be run on the Mac mini M4 32GB?
- K2 Horizon 0.9B, Qwen3.8 27B, K2 Horizon MoVA 36B-A4B and others with a 4K input and the recommended format. Required memory varies by model and context length.
- What is the local LLM power of the Mac mini M4 32GB?
- Sustained load is about 48 W, with an actual range of 32–63 W.
- Are the displayed token speeds ground truth?
- This is a range aligned to collected benchmark measurements under the same conditions. Combinations without a matching measurement are estimated from the nearest result and vary with runtime, cooling, quantization file and context length.
Equipment to compare together
Using 12B? Compare 24GB too
Mac mini M4 24GB
If you summarize short documents and ask about small sections of code, first check whether the model you plan to use gives useful answers. If a 12B Q4 model does the job, 32GB is worth considering only when your work needs more memory headroom.
Compare waiting times for 27B
Mac mini M4 Pro 48GB
When you repeatedly read documents and edit code with a 27B model, each wait matters as well as capacity. This page uses the 20-core GPU, 48GB configuration. Distinguish it from less expensive listings with a 16-core GPU.
Work that requires CUDA
RTX 5090 32GB
Compare this card if you repeatedly generate images or run 27B–35B inference and want shorter waits. But 32GB is still a limit. Buying on compute performance alone, without checking the model, input and image resolution, may leave you offloading again.