
Mac mini M4 Pro 64GB Integrated memory 64GB · Usable space for model approximately 56GB
Previous generation high-capacity configuration with 64GB integrated memory in a small body. Ideal for comparing prices of new and refurbished products in stock.
Speed and memory for the same model
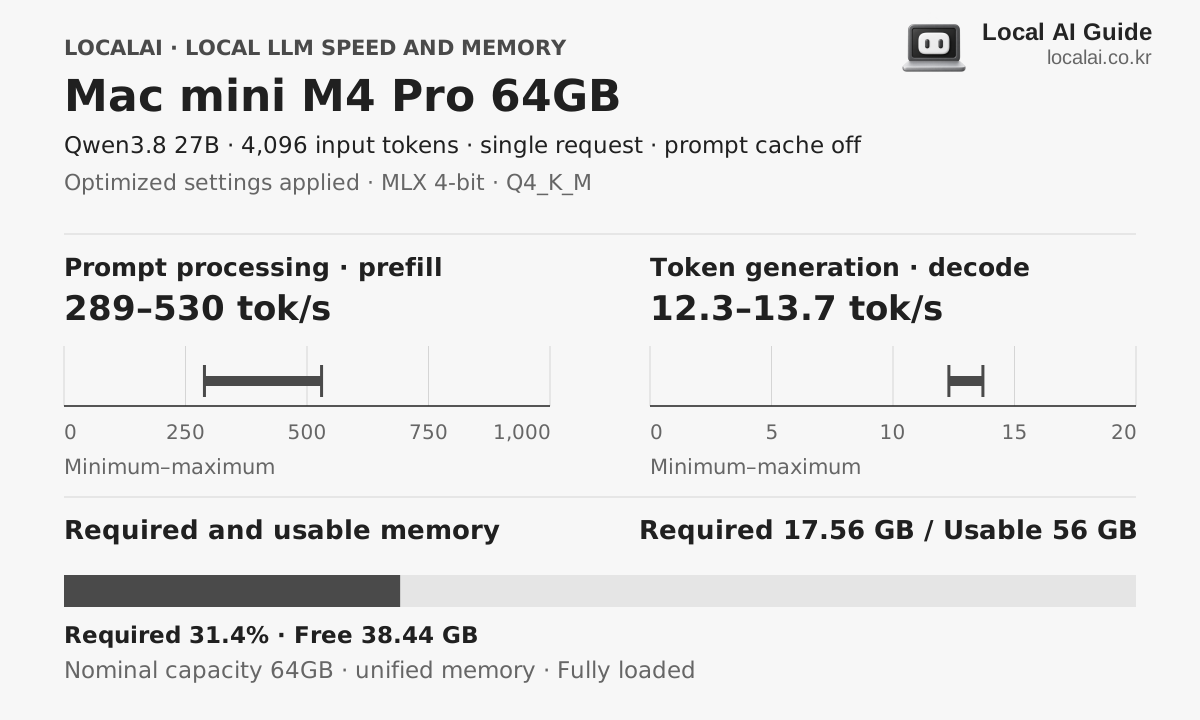
Hardware core specifications
- Available memory
- 56GB
- Memory bandwidth
- 273GB/s
- Estimated sustained LLM load
- About 95W
- Korean price range (KRW)
- 412 × KRW 10,000–620 × KRW 10,000
Who it fits
- Utilizes 56GB of available memory
- Quiet finished product composition
- K2 Horizon MoVA 36B-A4B-level local inference
Skip it if
Unified memory is advantageous for loading large models, but CUDA-specific tools and multi-GPU workflows should be explored separately.
Recommended format for each device 4K input
The model you will experience with this equipment
K2 Horizon 0.9B
Required 1.03GB · spare time
MLX 4-bit
Decode
370.9 ~ 412.1 tok/s
First token
0.76 to 1.7 seconds
K2 Horizon MoVA 36B-A4B
recommendedRequired 21.94GB · spare time
MLX 4-bit
Decode
83.3 ~ 92.5 tok/s
First token
4.5 to 9.8 seconds
Actual speed varies with runtime version, cooling, context length and quantization file.
On sales pages, look at memory before chips.
The model and speed assumptions above change if the product is not the 64GB configuration.
Frequently asked questions
- What LLM can be run on the Mac mini M4 Pro 64GB?
- K2 Horizon 0.9B, K2 Horizon MoVA 36B-A4B and others with a 4K input and the recommended format. Required memory varies by model and context length.
- What is the local LLM power of the Mac mini M4 Pro 64GB?
- Sustained load is about 95 W, with an actual range of 65–125 W.
- Are the displayed token speeds ground truth?
- This is a range aligned to collected benchmark measurements under the same conditions. Combinations without a matching measurement are estimated from the nearest result and vary with runtime, cooling, quantization file and context length.
Equipment to compare together
similar memory
Mac mini M4 Pro 48GB
When you repeatedly read documents and edit code with a 27B model, each wait matters as well as capacity. This page uses the 20-core GPU, 48GB configuration. Distinguish it from less expensive listings with a 16-core GPU.
similar memory
Mac mini M4 32GB
Consider this configuration if you want to run 27B Q4 without building a new PC. Moving up makes sense if 24GB was running out of memory. If the model and cache already fit, however, choosing 32GB does not make the chip itself faster.
similar memory
Mac mini M6 32GB
If you plan to run a Qwen 27B-class Q4 model while keeping a browser or document app open, the 32GB configuration belongs on the shortlist. It has the same 170GB/s memory bandwidth as the 24GB M6, so the reason to buy 8GB more is the headroom left after loading the model. It launched on September 22, 2026, and can now be compared using current configurations and prices.