
2× NVIDIA GeForce RTX 3090 NVLink 48GB Configuration to run a model across two devices · Total memory 48GB
Dual GPU configuration with 2× 24GB VRAM (48GB combined, 1,872 GB/s combined local bandwidth) and 3rd generation NVLink (112.5 GB/s bi-directional). When supporting tensor/pipeline parallelism, the 70B class model is fully loaded.
Speed and memory for the same model
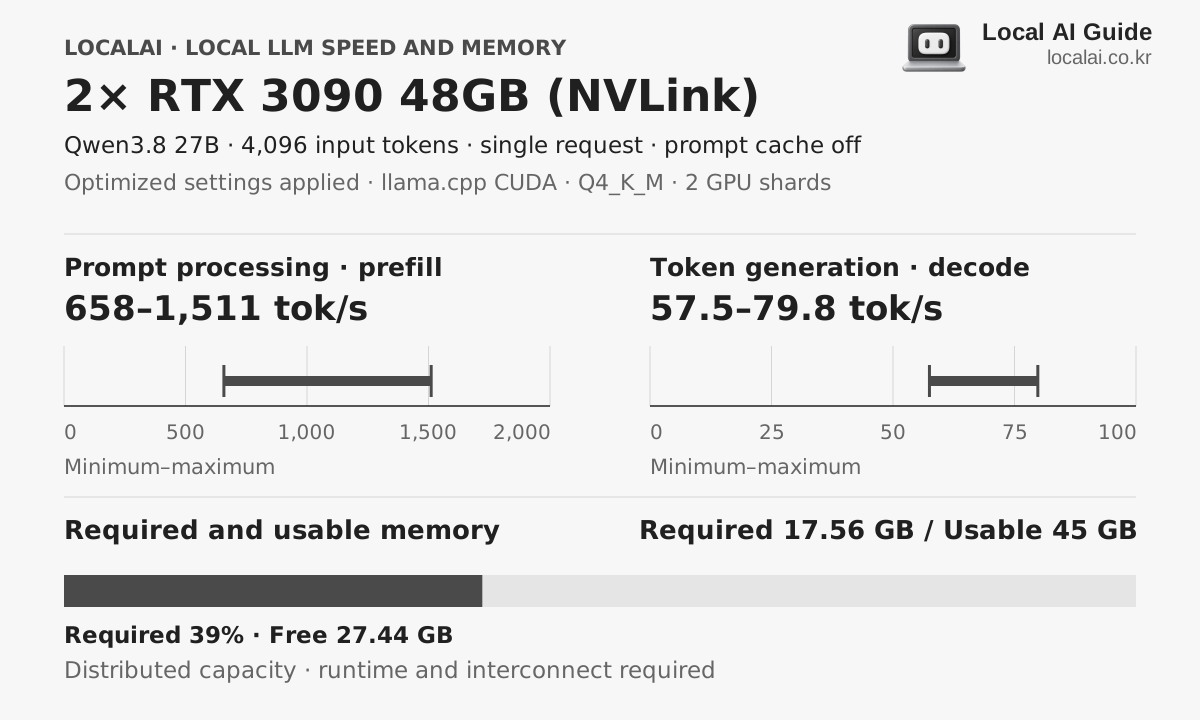
Hardware core specifications
- Available memory
- 45GB
- Memory bandwidth
- 1872GB/s
- Estimated sustained LLM load
- About 780W
- Korean price range (KRW)
- 478 × KRW 10,000–478 × KRW 10,000
Who it fits
- Utilize 45GB of available memory
- Two-Device Distributed Inference
- Comparison of Qwen3.8-Flash-Next-grade models
Skip it if
Even if you connect two devices, the memories are not automatically merged into one. Distributed runtime support and interconnect bottlenecks must be checked together.
Recommended format for each device 4K input
The model you will experience with this equipment
K2 Horizon 0.9B
Required 1.03GB · spare time
llama.cpp CUDA · Q4_K_M · GPU split into 2 pieces
Decode
1729.3 ~ 2401.8 tok/s
First token
0.17 to 0.38 seconds
Qwen3.8-Flash-Next
recommendedRequired 97GB · tight
Strata 0.1.40 · IQ3_S · MTP-4 · pipeline-windows 2 · SSD PLE
Decode
67.1 ~ 184.9 tok/s
First token
1.3 to 3.6 seconds
Actual speed varies with runtime version, cooling, context length and quantization file.
On sales pages, look at memory before chips.
The model and speed assumptions above change if the product is not the 48GB configuration.
Frequently asked questions
- What local LLM can be run on 2× RTX 3090 48GB (NVLink)?
- K2 Horizon 0.9B, Qwen3.8-Flash-Next and others with a 4K input and the recommended format. Required memory varies by model and context length.
- What is the power consumption of a local LLM using 2× RTX 3090 48GB (NVLink)?
- Sustained load is about 780 W, with an actual range of 650–920 W.
- Are the displayed token speeds ground truth?
- This is a range aligned to collected benchmark measurements under the same conditions. Combinations without a matching measurement are estimated from the nearest result and vary with runtime, cooling, quantization file and context length.
Equipment to compare together
similar memory
Mac mini M4 Pro 48GB
When you repeatedly read documents and edit code with a 27B model, each wait matters as well as capacity. This page uses the 20-core GPU, 48GB configuration. Distinguish it from less expensive listings with a 16-core GPU.
similar memory
Mac mini M4 32GB
Consider this configuration if you want to run 27B Q4 without building a new PC. Moving up makes sense if 24GB was running out of memory. If the model and cache already fit, however, choosing 32GB does not make the chip itself faster.
similar memory
Mac mini M6 32GB
If you plan to run a Qwen 27B-class Q4 model while keeping a browser or document app open, the 32GB configuration belongs on the shortlist. It has the same 170GB/s memory bandwidth as the 24GB M6, so the reason to buy 8GB more is the headroom left after loading the model. It launched on September 22, 2026, and can now be compared using current configurations and prices.