
Model setup recipes
Last updated
Gemma 4 26B-A4B MTP: How Speed Changes Between One and Many Requests
Compare MTP requests on Gemma 4 26B-A4B
Gemma 4 26B-A4B is a MoE1 model that takes documents or images with questions and generates text answers. It computes with about 3.8B of its 25.2B parameters per token2; running it requires the full weights and context KV cache3. With MTP4, an assistant proposes upcoming token candidates for the target to verify, potentially reducing answer-generation time.
First run the target model alone and check that it processes your document through to completion. Then add an assistant drafter in the same MLX-VLM environment and send the same question. Comparing the wait for the first token separately from subsequent generation shows whether MTP helps your workload.
Separate full weights from active computation
If you want to find changes in a long design document, do not estimate memory from the model's ‘3.8B active’ figure alone. Only some experts activate for a token, but the runtime5 prepares all roughly 25.2B weights from which to select. Context KV cache and operating-system/runtime memory are additional.
The Q4 desktop path uses an 8K context and one concurrent request as a comparison starting point, not as an optimal setting for every device. First check that a real document question completes with target-only, then add the assistant drafter only after the baseline is stable.
The Gemma 4 MTP drafter Google announced in May 2026 is an assistant checkpoint6 paired with the target. It is not replaced by an arbitrary small chat model; the app and runtime must support the assistant format and MTP.
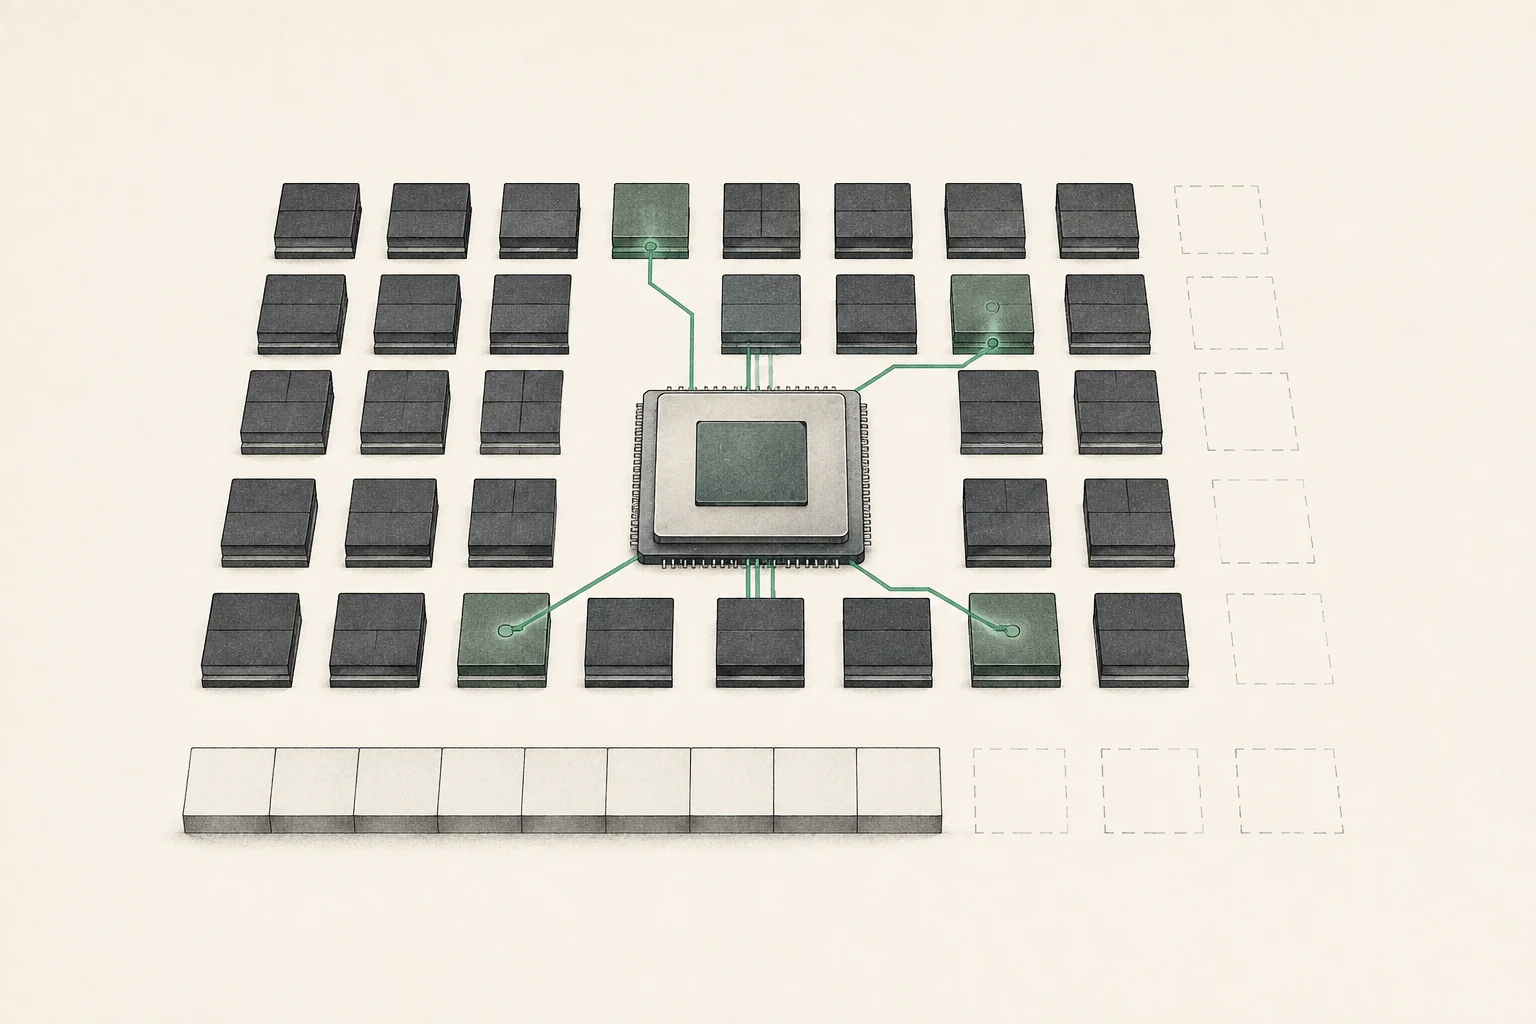
Understand how MTP verifies draft candidates
In ordinary generation, the target computes one next token at a time. With MTP, a four-layer assistant drafter proposes upcoming token candidates, and the target verifies the bundle. If candidates match, one target computation can confirm several tokens and reduce decode7 waiting. Rejected candidates are replaced by target output.
The gain depends on how often drafts match the next tokens. Frequent acceptance can reduce decode time, while low acceptance adds draft computation and memory. If prefill8 for a long input dominates total waiting, improving generation alone may not greatly reduce end-to-end response time.
In its May 2026 announcement, Google reported a routing challenge at batch 1 on Apple Silicon and observed up to about 2.2× improvement at batch 4–8. Those results apply to the announcement's model, runtime, and request-batch conditions. Do not generalize them to a single request on a personal Mac or a different quantized app; record batch size9 and prompt/output token counts.
| Measurement stage | Question | Conditions to record |
|---|---|---|
| Model load | Does the target and assistant fit in memory? | Cold start, weight precision, peak memory |
| Prefill / TTFT | How long to read a long document and produce the first token? | Input tokens, warm/cold prefix, context |
| Decode | How quickly does generation continue after the first token? | Output length, accepted tokens, temperature |
| End-to-end request | How long from start to completion? | Batch, concurrency, warmups and repetitions |
Create a target-only baseline in MLX-VLM
This exercise first runs the same BF1610 target in MLX-VLM on Apple Silicon, then compares it with MTP using the paired BF16 assistant drafter. You need memory for both model files. Do not mix in Q4 LM Studio results; compare target-only and MTP within the same MLX-VLM runtime.
The first run may include model-download and loading time. After confirming load completion and a response, record three target-only runs with the same prompt11 and 256-token limit. Then run the command with the drafter under the same conditions. Check logs for assistant loading and draft-acceptance statistics.
Check that both runs answer and that MTP logs show acceptance information. If the output differs at temperature 0, record that and inspect runtime version, checkpoints, prompt template, and logs. Keep published efficiency claims separate from your own measurements.
python -m pip install -U mlx-vlm
mlx_vlm.generate --model mlx-community/gemma-4-26B-A4B-it-bf16 --prompt "Design note: The Northstar launch moves from May 12 to May 19. The API freeze remains May 5. Summarize the changed date and the unchanged milestone." --max-tokens 256 --temperature 0
mlx_vlm.generate --model mlx-community/gemma-4-26B-A4B-it-bf16 --draft-model mlx-community/gemma-4-26B-A4B-it-assistant-bf16 --draft-kind mtp --draft-block-size 6 --prompt "Design note: The Northstar launch moves from May 12 to May 19. The API freeze remains May 5. Summarize the changed date and the unchanged milestone." --max-tokens 256 --temperature 0
Measure single requests and batch processing separately
Run target-only and MTP as single requests. Use the same prompt and output limit, warm up, then repeat at least three times; separate initial file loading from warm measurements. Record median time, omissions, accepted tokens, and peak memory. With long inputs, track first-token and end-to-end time as well as generation speed.
A server handling multiple requests is a separate test. When changing batch, adjust only prompts, output length, and request count; keep model files and draft block size fixed. For individual responsiveness, single-request latency is the main measure; for server capacity, track per-request latency and total throughput12 together.
If acceptance is low or draft overhead makes a workload slower, target-only may be the better configuration for that task. Higher throughput alone does not mean each user's answer arrives sooner; decide using your real request mix.
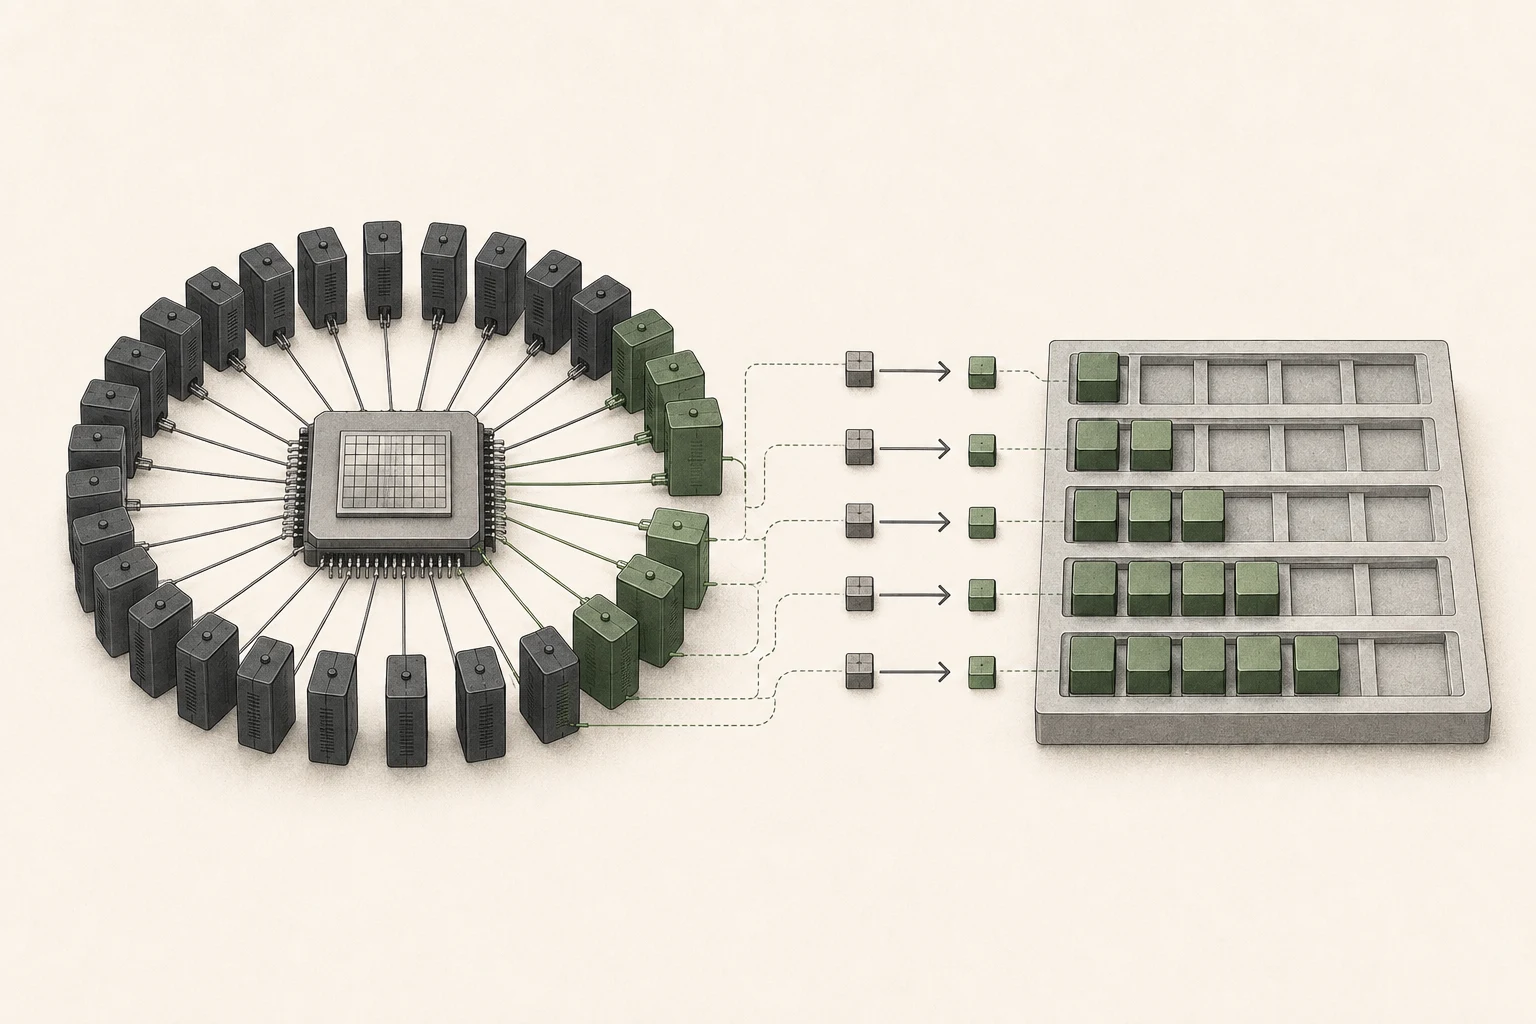
Choose the feature based on memory or generation wait
QAT changes weight representation and compression efficiency to reduce memory needs; MTP verifies candidate tokens during generation to reduce waiting. To use MTP with a QAT target, confirm a target/drafter pair that supports both features. File names containing QAT or MTP do not establish compatibility.
If the target itself does not load, first address file precision and memory headroom. Compare MTP when the target works and answer generation is the main bottleneck. If input reading takes longest, inspect prefill and cache conditions first. If target-only is faster, do not add the assistant for that workload.
Check the announcement and runtime documentation
The MTP mechanism and Apple Silicon batch results refer to conditions Google published in May 2026. The CLI13 example follows MLX-VLM's published command and Gemma 4 pairing. This guide does not add device-specific benchmarks; record personal measurements with their model, runtime, and request conditions.
Terminology notes
MoE — A model architecture that selects some of several expert subnetworks for each input. Total parameters can differ from the number activated for one token.
Back to the textToken — A unit into which a model divides input or output for processing.
Back to the textKV cache — Memory that stores attention keys and values from earlier tokens for reuse during later token generation. Its size depends on context length and batch size.
Back to the textMTP — A training objective or model component for predicting multiple future tokens at once. In speculative decoding, those predictions can be proposed as candidate tokens.
Back to the textRuntime — The software environment that provides facilities needed while a program runs. In local AI, it can also refer to a model execution engine.
Back to the textCheckpoint — A file containing saved model weights and related state. Versions or tasks in one model family may use different checkpoints.
Back to the textToken decoding — The stage that generates successive output tokens using the input and the response produced so far.
Back to the textPrefill — The stage where an LLM reads the input prompt and computes representations for its tokens. Longer prompts contain more tokens to process.
Back to the textBatch size — The number of inputs or requests processed together in one batch.
Back to the textBF16 — A 16-bit floating-point format for model values. Its exponent has the same width as FP32, giving it a similarly wide value range.
Back to the textPrompt — The input text sent to a model. For generative models it describes the desired result and strongly shapes the output.
Back to the textThroughput — The amount of work processed or generated over time. Comparisons need the unit, such as tokens per second or requests per second.
Back to the textCLI — Short for Command-Line Interface: operating a program by entering commands in a terminal.
Back to the text
Frequently asked questions
- What should you check first in this article?
- Gemma 4 26B-A4B is a MoE model that takes documents or images with questions and generates text answers. It computes with about 3.8B of its 25.2B parameters per token; running it requires the full weights and context KV cache. With MTP, an assistant proposes upcoming token candidates for the target to verify, potentially reducing answer-generation time.
- How much memory does it need?
- This exercise first runs the same BF16 target in MLX-VLM on Apple Silicon, then compares it with MTP using the paired BF16 assistant drafter. You need memory for both model files. Do not mix in Q4 LM Studio results; compare target-only and MTP within the same MLX-VLM runtime.
Serving recipe
Settings for your hardware
For one user
Choose your hardware to see the launch command and settings you can adjust.
Profile
Apple MacBook Pro M5 Pro (64GB)
Memory fitsRecommended runtime: LM Studio (4-bit MLX (a different format from GGUF Q4_K_M)) · Documented runtime settings
For your first run or reliable everyday use
Profile context length
16,384 tokens
A starting setup based on the runtime documentation. Follow the steps below and compare speed as you make changes.
Estimated decode speed
26.9 ~ 65.4 tok/s
Estimate for one user
Estimated TTFT
8.8 ~ 21.5 s
Prefill: 765 ~ 1,861 tok/s
Estimated memory use
About 16.34GB / 56GB
Remaining margin: approx. 39.7GB
Server address
http://127.0.0.1:1234
Local only · 127.0.0.1
Estimates use the calculator’s recommended quantization and acceleration with 16,384tokens. They are not measurements of the configuration above.
Settings in this profile
| Value | Why this setting |
|---|---|
| Weights4-bit MLX (a different format from GGUF Q4_K_M) | Use an MLX model directory. This is a different file format from Q4_K_M GGUF. |
| Check input length16,384 | Check both the context-length setting in lms load and the context actually loaded. |
| KV cacheCheck model settings | This launch command does not set the KV cache precision. |
| Prefill batch sizeCheck runtime settings | Do not use llama.cpp's batch-size and ubatch-size values as substitutes for MLX settings. |
| Concurrent requests1 | Measure the speed of one request, separately from the combined throughput of multiple requests. |
| Memory headroom2 GB or more | After loading the model, check actual memory use and whether the system is swapping. |
MBP M5 Pro 64GB Run command (LM Studio)
# lms ls에서 확인한 MLX 4비트 모델 식별자를 입력
MODEL_ID=""
lms ls
: "${MODEL_ID:?MLX 모델 식별자를 입력하세요}"
lms load "$MODEL_ID" --gpu=max --context-length=16384
lms server start --port 1234Checks after startup
- 01Check the startup log for completed model loading and the actual context length.
- 02After warming up, send one request at a time. Use three different inputs of the same length to record fresh-input processing time.
- 03Record repeated-input results separately as cache-reuse runs. Do not combine them with fresh-input results.
- 04Record prefill tok/s, decode tok/s and peak memory together, then change one setting at a time.
Trade-offs
- Conservative context and concurrency settings may produce less than the hardware's maximum throughput.
Adjust one item at a time
Speed tuning, step by step
If several values are changed at once, it is difficult to find the cause.
- STEP 1
Save a baseline
Record first-input and cache-reuse runs separately, three times each. Compare prefill, decode and peak memory together.
When to stop: Do not move on if there are errors or less than 2GB of memory headroom.
- STEP 2
Tune prefill chunk size
Increase in steps of 1,024 → 2,048 → 4,096, comparing TTFT and peak memory on long inputs.
When to stop: Revert to the previous value if TTFT does not improve or peak memory rises sharply.
- STEP 3
KV Cache Tuning
Only when you need more context, compare Q8 cache against the F16/BF16 baseline using the same question.
When to stop: Keep the default precision if the output changes or you already have enough context.
- STEP 4
MTP/speculative decoding
Enable it only for supported models. Test code and prose separately, measuring acceptance rates and actual decode tok/s.
When to stop: Turn it off if the median of three runs does not improve on the baseline.
- STEP 5
Context expansion
Double context length at each step until you reach what you need. Check retrieval from the middle of the input and whether swapping occurs.
When to stop: Reduce by one step if retrieval accuracy drops or swapping or memory compression starts.
Submit a measurement from my hardware
Import a JSON file with at least three runs under the same conditions. The file stays in this browser until you submit it.
Include only hardware, model, runtime settings and measurements. Do not include prompts, responses, raw logs or file paths.
If you do not have a measurement file, use the tool with your running local server. It requires Node.js 20 or later and does not upload results automatically.
These are reviewed community submissions, not measurements made by this site.
Report a setup issue
Tell us where this setup failed. Only the site administrator can read your report.
Setup being reported · MBP M5 Pro 64GB · Gemma 4 26B-A4B (MoE) · Balanced
Change log
These entries record changes to the site's guidance. They do not automatically check your installed engine or model version.
Corrected model formats and runtime settings for Mac
Separated the Mac MLX path from GGUF Q4_K_M and aligned the engine name, model format and command. KV-cache precision and prefill batching that the command does not specify are now marked for checking in the model or runtime settings.
Also removed MLX speed profiles that implied a larger batch despite leaving the command unchanged.
Separated uncached-input and cache-reuse records
Updated the checks to record first-time inputs separately from repeated inputs. Cache effects are not folded into uncached prefill throughput or hardware differences.
Added saving and reopening hardware profiles
Runnable profiles can now be saved with their hardware selection in this browser, up to five entries, and reopened from the guide directory. A notice prompts you to recheck before running if the published settings have changed or the profile is no longer available.
Added links to runtime explanations
Engine names in the settings now link to the corresponding runtime guide. Paths without an identified engine are not linked to a guessed program.