
Executable programs and extensions
Last updated
What Is LiLiCorr? Speculative decoding for Bolt and Super VL
LiLiCorr uses drafter files and recipes matched to each target and runtime.
LiLiCorr is a speculative-decoding1 drafter that scores connections among candidate next tokens2 and selects a draft path for a target model. The required drafter files and settings vary by target and runtime3. Bolt uses a llama.cpp GGUF4 pair; Super VL uses a DGX Spark vLLM pair, so this guide separates their files, commands, and published metrics.
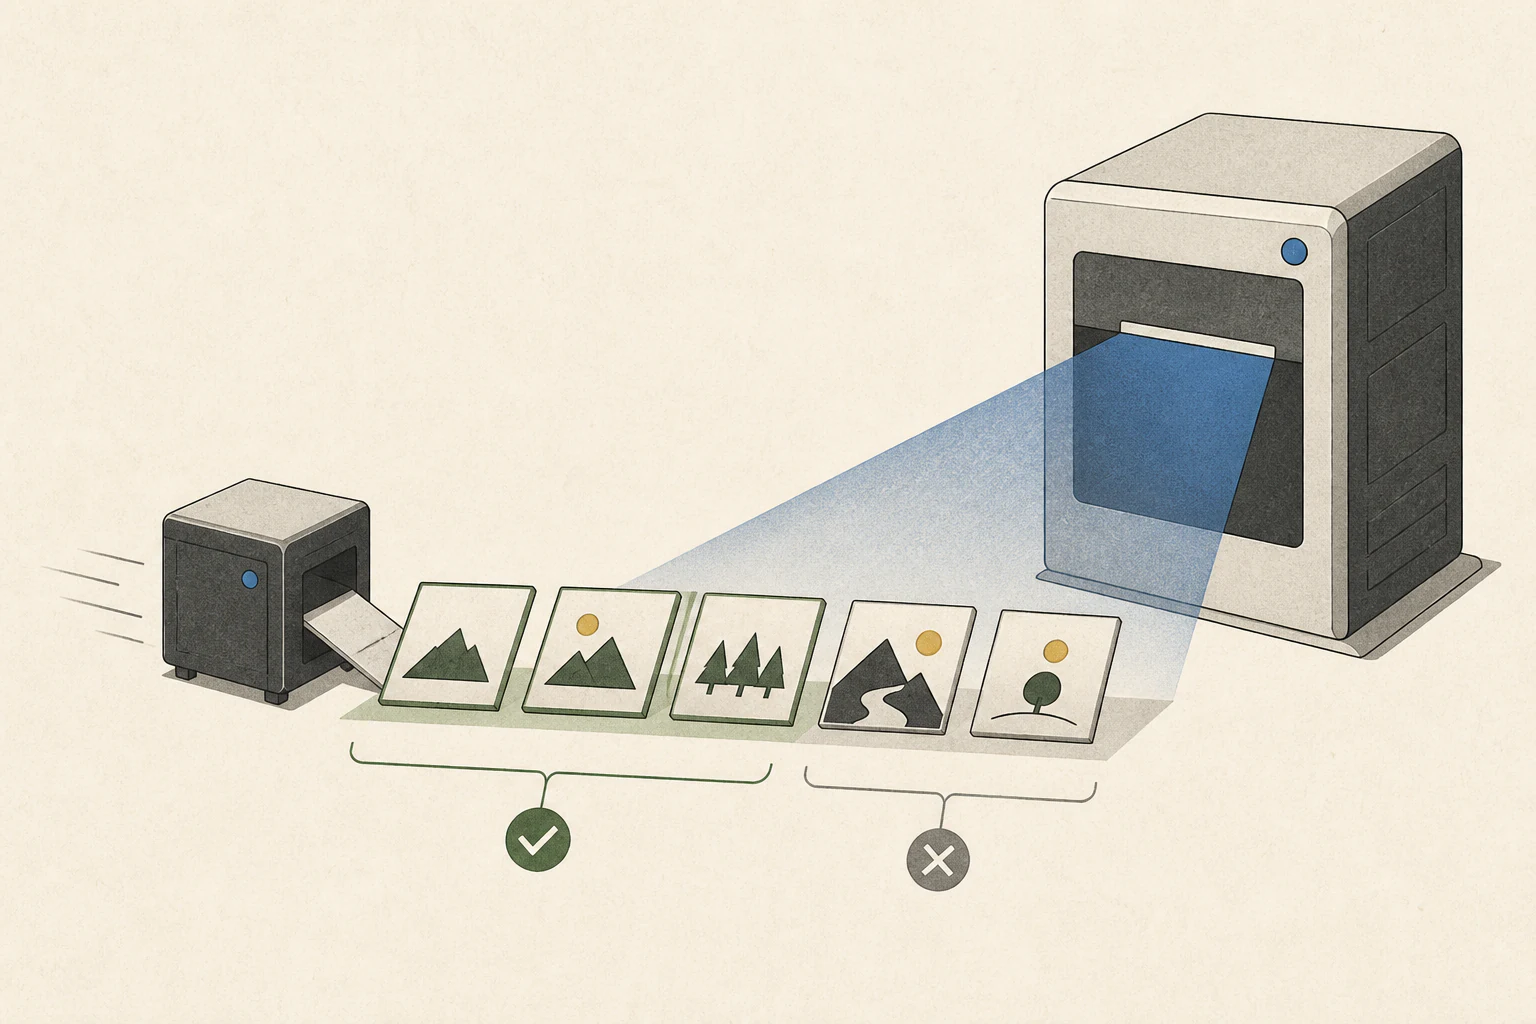
When a target model generates one token at a time, it repeats work for each next token. Speculative decoding lets a drafter propose candidates first, then has the target verify a block and accept the matching run together. LiLiCorr scores connections between candidates to choose a draft path. NVIDIA LiLiCorr research
LiLiCorr still requires a drafter file and runtime recipe matched to the target. Bolt uses a GGUF target/drafter pair in llama.cpp; Super VL uses an NVFP45 target and LiLiCorr drafter in vLLM on DGX Spark. Prepare each pair and its settings from the corresponding model card.
LiLiCorr selects candidates that fit together
A parallel draft model proposes next-token candidates at several positions at once. LiLiCorr scores the connections between candidates to choose a path for the target model to verify. LiLiCorr method
Speed gains vary with the drafter and target pairing, input style, and number of concurrent requests. Bolt runs with llama.cpp and Super VL with vLLM, so use the settings for each path.
Bolt: connect the GGUF drafter in llama.cpp
For Bolt 74B-A9B, prepare both the target GGUF and the LiLiCorr drafter GGUF. Connect the llama.cpp server with --spec-type draft-dflash and --spec-draft-model to use the two files.
NVIDIA lists a 32 GB recipe for a 128 GB RTX Spark or a GeForce RTX with at least 48 GB of VRAM6. It uses a 262,144 context, one concurrent sequence, and up to 7 draft tokens.
For a 64 GB RTX Spark or a GPU7 with at least 32 GB of VRAM, NVIDIA lists a 28 GB recipe with a 65,536 context, one sequence, up to 6 draft tokens, and a Q8_0 KV cache8. Bolt GGUF model card and recipes
Download the target GGUF and LiLiCorr drafter GGUF. Replace the paths in the first code block with the actual file locations and run it in your shell. Once both variables are set, use the next command to pair the files. Apply the context, cache, and draft-token options from the model-card recipe for your GPU.
export BOLT_GGUF="/absolute/path/to/target.gguf"
export LILICORR_GGUF="/absolute/path/to/lilicorr-drafter.gguf"llama-server -m "$BOLT_GGUF" \
--spec-type draft-dflash \
--spec-draft-model "$LILICORR_GGUF" \
--host 127.0.0.1Super VL: use vLLM LiLiCorr on DGX Spark
On DGX Spark (GB10), use NVIDIA's Super VL LiLiCorr profile. Run the NVFP4 target and a separate ...NVFP4-LiLiCorr drafter inside the vLLM container.
The NVIDIA settings use one concurrent sequence, 7 draft tokens, 0.75 GPU memory utilization, and 8,192 batched tokens. The vLLM recipes list this DGX Spark LiLiCorr path separately from the native MTP9 path for RTX PRO 6000. Super VL LiLiCorr model card
The target also has a native MTP path. MTP uses prediction heads inside the target, while LiLiCorr requires a separate drafter checkpoint10; keep their speculative method and model arguments distinct. Start with a short text request and confirm the API11 model name, then add image input and your usual concurrency while recording memory use and completion time.
Read the workload alongside each metric
NVIDIA's study reports that LiLiCorr increased acceptance length by 9–19% and greedy decoding12 throughput13 by 4–13% over vanilla DFlash trained on the same data. The comparison tested models including Qwen3 4B and 8B on H100 GPUs.
The Super VL LiLiCorr card's SPEED-Bench reports acceptance lengths of 4.74 (temperature 0) and 4.36 (temperature 1), averaged across three seeds with draft length 7, 880 prompts14, and 64 concurrent requests.
The 64 is the benchmark load. The DGX Spark serving recipe sets --max-num-seqs 1. Acceptance length means the average number of accepted tokens.
Research results · Model card measurements
A separate published Bolt measurement used a 128GB Surface Laptop Ultra with RTX Spark, Windows 11 ARM, and llama.cpp. Bolt IQ2_XXS with LiLiCorr recorded 83.99 TPS on AIPerf SPEED-Bench-Coding and 600.80 seconds for AA-AgentPerf Local replay. These measurements apply to that Bolt setup and workload. Bolt measurement conditions
Terminology notes
Speculative decoding — A generation method in which a draft model, MTP head, or repeated-context lookup proposes output candidates for the main model to verify and accept.
Back to the textToken — A unit into which a model divides input or output for processing.
Back to the textRuntime — The software environment that provides facilities needed while a program runs. In local AI, it can also refer to a model execution engine.
Back to the textGGUF — A file format for model data, widely used by llama.cpp-based tools.
Back to the textNVFP4 — A 4-bit floating-point data format defined by NVIDIA. Support depends on GPU generation, model, and software implementation.
Back to the textVRAM — Memory used by a graphics card’s GPU to store model weights and intermediate values.
Back to the textGPU — A processor designed to handle many calculations in parallel. It performs model computations during AI inference.
Back to the textKV cache — Memory that stores attention keys and values from earlier tokens for reuse during later token generation. Its size depends on context length and batch size.
Back to the textMTP — A training objective or model component for predicting multiple future tokens at once. In speculative decoding, those predictions can be proposed as candidate tokens.
Back to the textCheckpoint — A file containing saved model weights and related state. Versions or tasks in one model family may use different checkpoints.
Back to the textAPI — A defined interface that lets other code call a program’s functions.
Back to the textToken decoding — The stage that generates successive output tokens using the input and the response produced so far.
Back to the textThroughput — The amount of work processed or generated over time. Comparisons need the unit, such as tokens per second or requests per second.
Back to the textPrompt — The input text sent to a model. For generative models it describes the desired result and strongly shapes the output.
Back to the text
Frequently asked questions
- What should you check first in this article?
- LiLiCorr is a speculative-decoding drafter that scores connections among candidate next tokens and selects a draft path for a target model. The required drafter files and settings vary by target and runtime. Bolt uses a llama.cpp GGUF pair; Super VL uses a DGX Spark vLLM pair, so this guide separates their files, commands, and published metrics.
- How much memory does it need?
- NVIDIA lists a 32 GB recipe for a 128 GB RTX Spark or a GeForce RTX with at least 48 GB of VRAM. It uses a 262,144 context, one concurrent sequence, and up to 7 draft tokens.
- When is it better not to choose this?
- The target also has a native MTP path. MTP uses prediction heads inside the target, while LiLiCorr requires a separate drafter checkpoint; keep their speculative method and model arguments distinct. Start with a short text request and confirm the API model name, then add image input and your usual concurrency while recording memory use and completion time.
- Where can you check the conditions and sources?
- For a 64 GB RTX Spark or a GPU with at least 32 GB of VRAM, NVIDIA lists a 28 GB recipe with a 65,536 context, one sequence, up to 6 draft tokens, and a Q8_0 KV cache. [Bolt GGUF model card and recipes](https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB-GGUF/blob/main/README.md)