read first
What Is a Local AI Agent? When It Makes Sense to Run One
Running on your computer does not mean every part of the workflow stays there.
A local AI agent1 does more than send prompts to a model: it can use permitted tools to find files and organize results. If you repeatedly search and summarize meeting materials, it can automate that workflow. The model can also run on your computer, but the agent and model do not have to share a machine. First decide which files and requests must stay local.
Start with one file organization task
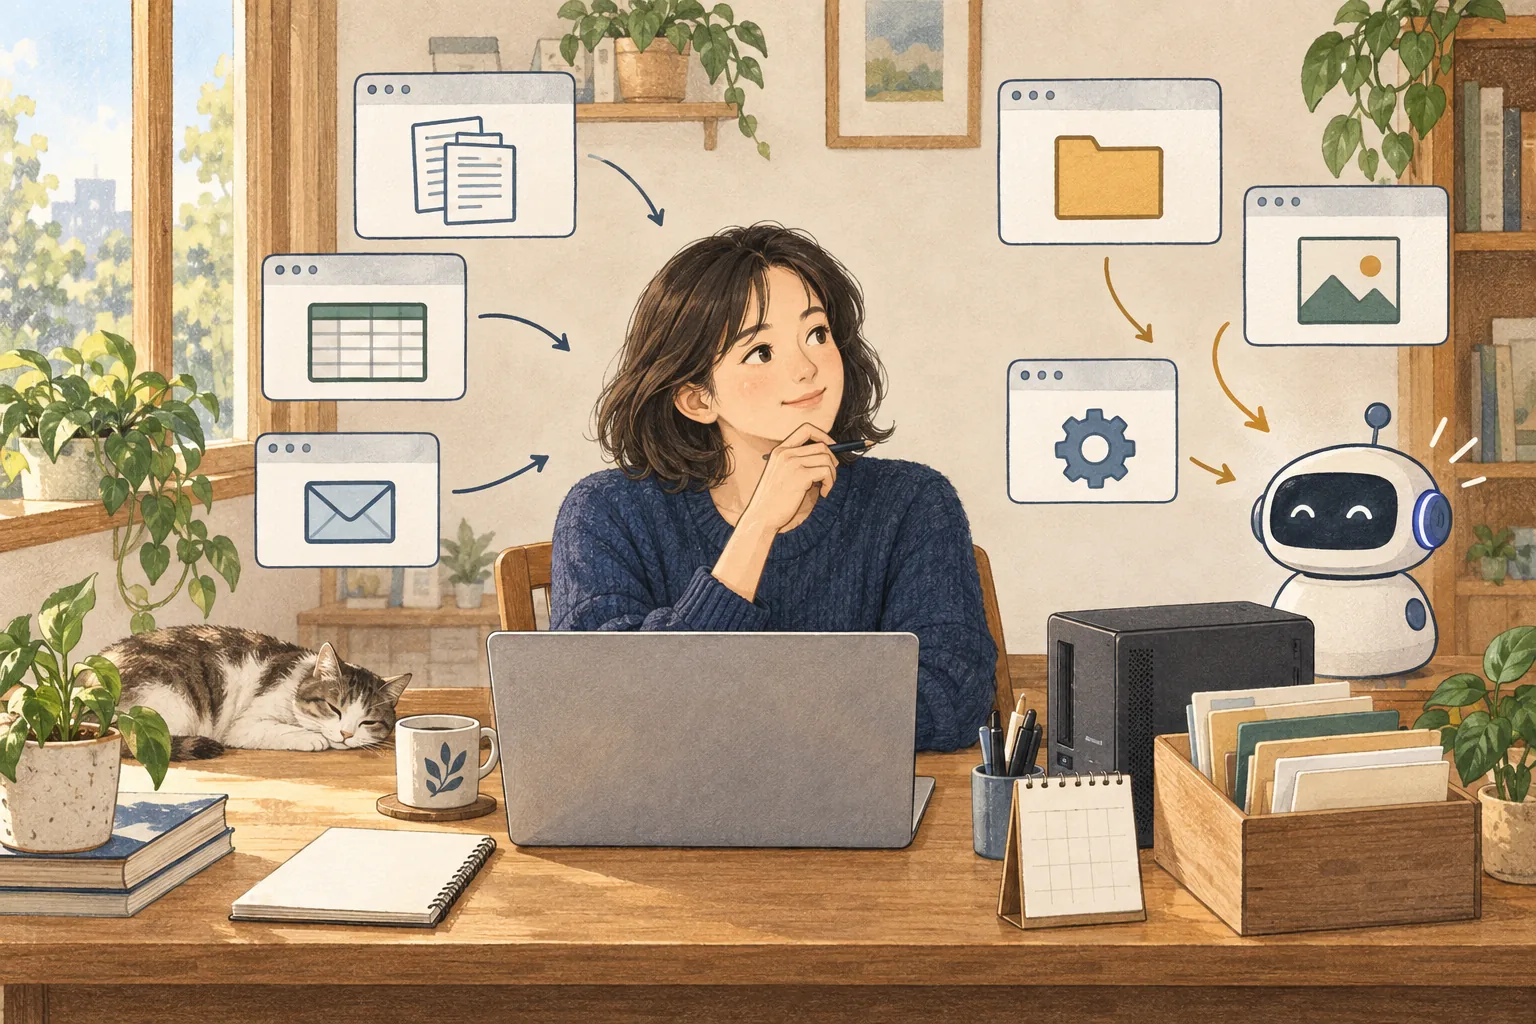
After a meeting, transcripts and notes sit in several folders. You often need to find them, extract decisions, and save a short summary. A chat model can summarize a transcript you paste in, but you still have to locate and open the file and provide its contents each time.
With access restricted to an approved folder, an agent can find a file, read it, and save a summary to a chosen location. For this workflow to operate safely, define the permissions for the agent, model, and file tools separately.
The model answers; the agent coordinates the work
A language model generates text from input. A model with tool-calling support can also produce a structured request naming a tool and its arguments. The model itself does not open a filesystem or sign in to a messenger. Software around the model must connect tools and permissions to provide those capabilities.
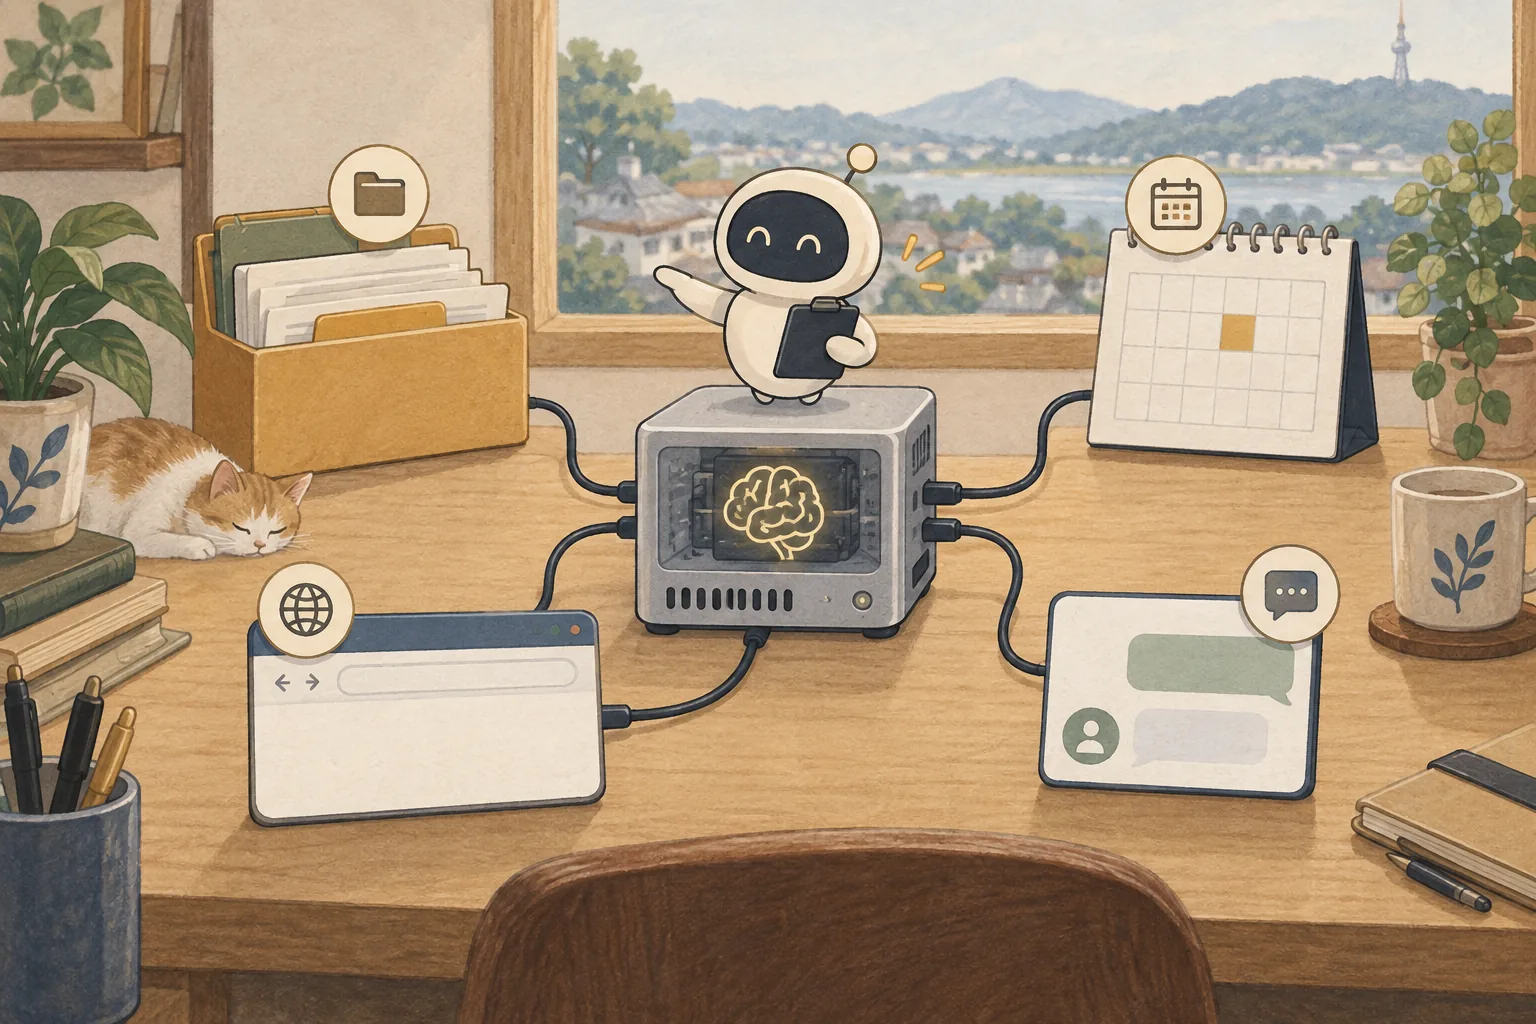
An agent runtime2 manages requests and sessions. When the model proposes a tool call3, the runtime sends it to the actual tool and returns the result to the model. This round trip can support several steps, such as listing files, opening a selected document, and composing an answer. If the tool-call format is incompatible with the model or server, ordinary chat may work while an agent task stops partway through.
Ask where each part of the workflow runs
Now consider what ‘local’ means for the same transcript task. The agent may run on a laptop while sending model requests to a remote API4. Or inference5 may run on your computer while the request arrives through an external channel such as Telegram or Discord. Add web search, speech recognition, or cloud backup and data may travel to those services too.
So ‘Do I use a local model?’ is not the only question. Check separately where the agent runtime runs, where the model endpoint6 is, whether connected tools use the internet, and where logs and attachments are stored. OpenClaw can connect a self-hosted Gateway7 to a local model, but the entire path, including channels and tools, does not become local automatically.
A recurring task needs a result you can verify
An agent is worth evaluating when a recurring task has a clear input scope and output format. For example, it could find this week’s meeting notes in a chosen folder, extract decisions and owners, and save a draft. That can reduce repeated file handling, while leaving a draft you can compare with the originals.
For one-off writing or questions where you can copy the answer yourself, ordinary chat may be simpler. If inputs vary and results are hard to evaluate, verification can take more effort than the automation saves. If many accounts are connected and nobody can manage their permissions, simplify the workflow before adding an agent.
Once tools are connected, permissions matter as much as data location
An agent that only reads notes has a different risk scope from one that can edit files and send them to colleagues. ‘It runs only on my computer’ does not address that difference. A document or webpage containing malicious instructions can influence the model, and broad tool access could let it change files or send information in response.
Begin testing with a copy or a separate work folder, and grant only reversible permissions such as reading files and drafting. Keep sending, deletion, and shell commands behind human review. Do not assume a product’s approval feature is equivalent to operating-system isolation; check its actual boundaries, network access, and mounted folders.
Choose only the components one task requires
Write down, in order, whether you want to automate transcript summaries, whether files may leave the computer, and whether you need messenger access. The agent and model can run on the same computer, or the agent can stay local while using a hosted model API. A model’s memory requirements and always-on runtime are separate from the agent program’s installation requirements.
The conclusion is not that a local agent is always better. It is worth trying when you have a verifiable recurring task, can narrow file and tool permissions, and can inspect the data routes you need. For simple questions, irregular inputs, or many permissions to manage, browser chat or a human-approved semi-automated workflow may be easier. Limit the first automation to reading a copy from one folder and producing a draft.
Start with an environment as simple as the task allows
A local agent does not need a messenger, shell, browser, and scheduling automation all at once. A first trial may need only desktop chat and one restricted folder. Whether you use it only while your computer is on or need access from elsewhere changes whether the Gateway belongs on your laptop or a separate server. A separate server also makes access control, updates, and backups more directly your responsibility.
A server at home does not eliminate external connections. If you create remote access, check authentication and network exposure; messenger credentials or API keys may also be stored on the host. If you close remote access and use a local UI only, you give up the convenience of using the agent from anywhere. This is not simply a cost or speed choice; compare accessibility needs with the risks you can manage.
Putting the agent runtime and inference server on one machine can simplify setup, but other applications may slow down while the model uses memory. A separate model server adds a network path between the agent and the server. Before choosing, decide whether access should stay inside your home network, which machine you can inspect when something fails, and whether there is room to download and update models. If sensitive files are copied to a separate server, its storage and backups are part of the data boundary too.
A short written requirement makes the choice easier. For example: ‘Read one folder of weekly meeting notes and save summaries as drafts. Do not send files to a remote model. A person will deliver the answer.’ That points to local inference and a file-reading tool while leaving external messenger integration and automatic sending out of the first setup. If you also allow a remote endpoint to compare model quality, restrict testing to public material or anonymized copies.
These requirements also provide a checklist when you expand the agent later. Confirm that ‘read-only’ matches the actual permissions, that results are written only to the draft folder, and that remote endpoints and test data are removed after a comparison. Repeating the same questions whenever you add a tool helps prevent the original data boundary from quietly expanding through configuration changes. If you can maintain these operating conditions, you can evaluate the agent’s practical value more clearly.
Terminology notes
AI agent — A program setup that selects tools, checks their results, and continues through steps toward a goal instead of only displaying a model response. Its actual scope depends on the connected model, tools, and permissions.
Back to the textRuntime — The software environment that provides facilities needed while a program runs. In local AI it can also refer to a model execution engine; a GPU runtime library and a complete serving app are different components.
Back to the textTool call — A structured request from a model for an external function such as reading a file, searching, or running a command. The agent runtime and its permission settings decide whether the request is actually executed.
Back to the textAPI — A defined interface that lets other code call a program’s functions. The term API alone does not imply sending data to an external server.
Back to the textInference — The process of using a trained model to compute an output for an input. Here, local inference means running the model on the user’s device.
Back to the textInference endpoint — The address and request interface through which a model server receives inference requests. It may be on the same computer, a LAN machine, or an external API, so both location and access controls matter.
Back to the textGateway — A program that receives requests across clients, channels, models, or tools and routes them to the appropriate path. It is not necessarily the server that runs the model itself.
Back to the text