
read first
Last updated
Local AI for PDFs: check the document before buying more memory
Check what the PDF reader extracted before adding memory
A local AI system for PDFs extracts or searches document text to produce answers. If a summary is wrong, first check whether a page of extracted text preserves the source's headings, sentence order, and table values. A larger model or more memory cannot repair corrupted input; compare retrieval methods and hardware only after the document is read correctly.
Imagine reviewing an 80-page service contract. Copy one page containing both body text and a table, then check whether headings, sentence order, and amounts remain attached to the correct entries. Do not just scan the numbers: verify that the value beside “annual fee” still belongs to that label. If reading order or table structure is already broken, the model will answer from misarranged content.
If copying produces nothing or only a page image, first check OCR1 or visual-input processing. Compare a scanned value with the source, for example, to see whether an 8 was read as a 3. You can test this step on a public document with a similar layout instead of a sensitive contract. Use successful extraction of a page's headings, sentences, and table as the pass condition; that makes later failures easier to separate from extraction problems.
Separate a full-document summary from a specific question
“Summarize all obligations in the contract” asks about the document's overall flow and relationships between sections. “When must I give notice to cancel auto-renewal?” asks for the relevant clause and any exception that changes its conditions. A retrieval-augmented generation2 (RAG) system finds relevant passages and supplies them to the answer instead of sending every page each time. If retrieval finds the cancellation clause but misses an exception elsewhere, a fluent answer can still be wrong.
Check not only whether a retrieved clause answers the question, but also whether it includes exceptions and related conditions elsewhere. If the notice period and required notice method appear in different sections, one passage may not be enough. Conversely, sending the whole document at once does not guarantee a complete summary: definitions and exceptions may become separated when chapter summaries are combined. Decide whether you need an overview or a specific answer with evidence before choosing input scope and retrieval.
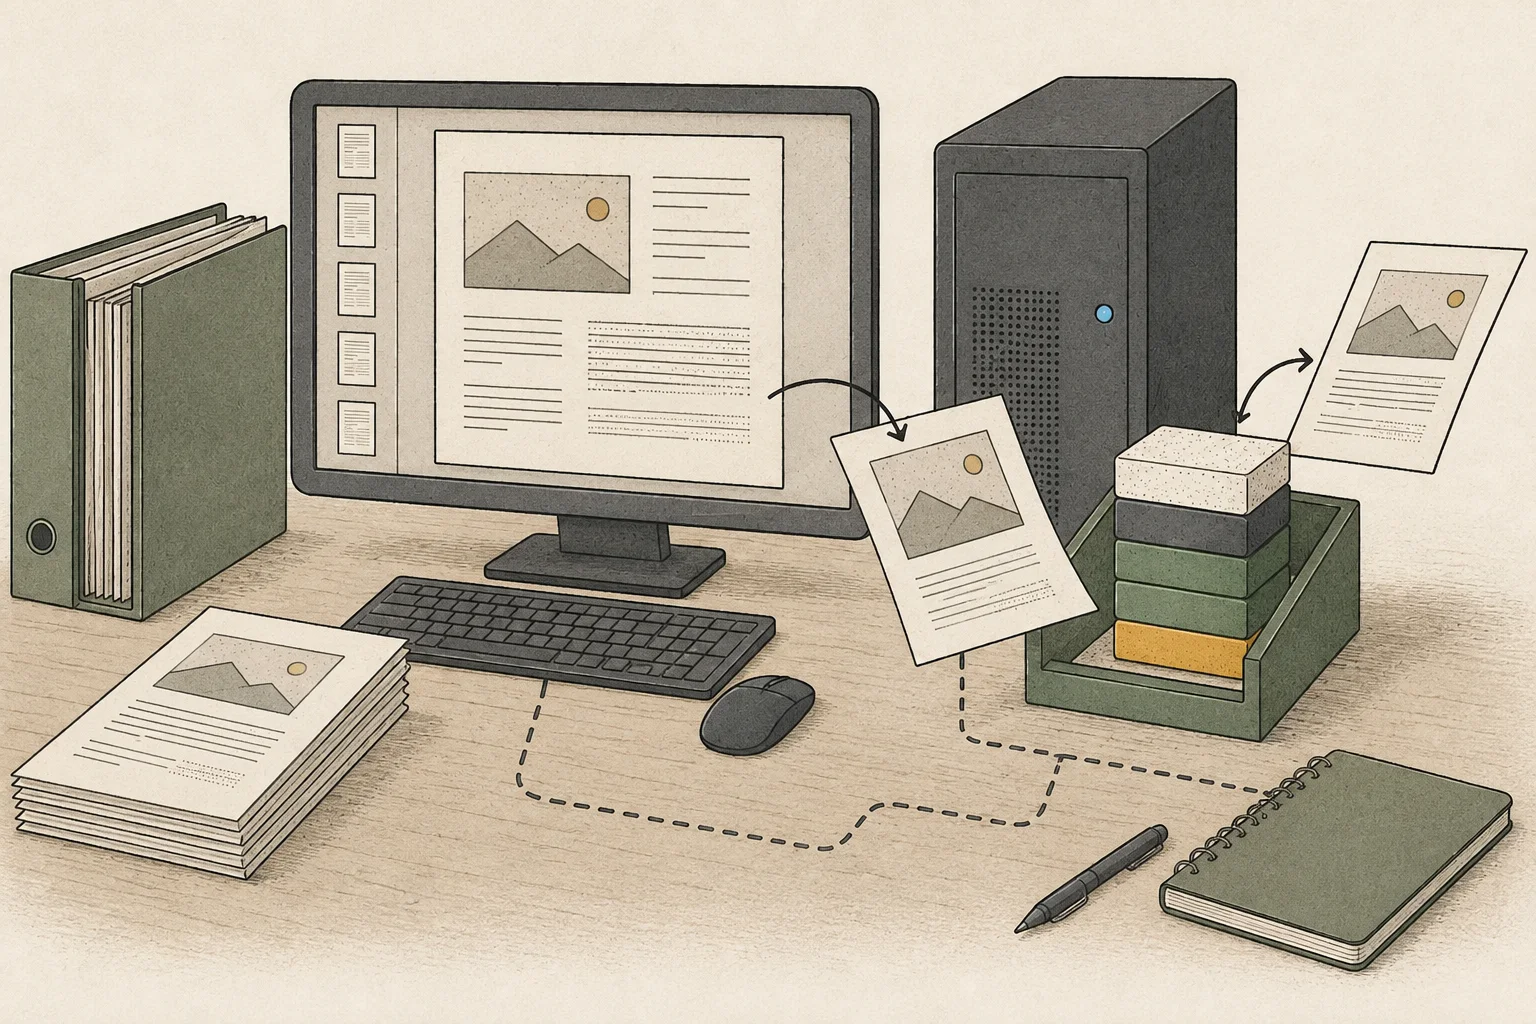
Separate waiting stages to locate the cause
The time from submitting a PDF to the first text may include file reading, text extraction, and prefill3, where the model processes input. Answer generation is the later decode4 stage. If pasted extracted text is quick but PDF upload is slow, inspect file handling or extraction first. If prepared text still produces a long first-answer wait as input grows, examine prefill.
The site's prefill comparison estimates how model input processing may feel; it does not reproduce PDF reading or OCR. In your app, record the time from selecting the PDF to answer completion separately from the time for submitting extracted text directly. Also separate time to first text from time to full completion to see whether file handling, input processing, or generation needs attention5.
Record known-answer questions with their source evidence
Choose three repeatable questions from the contract: the renewal notice date, a specific amount and unit in the fee table, and a support hour that the contract does not state. Locate the answers in the source in advance. For the last question, check whether the model explains that the information is absent instead of inventing a time. Reusing the same questions and answers lets you compare changes to models or retrieval scope.
Even when an answer includes a page or clause number, open that location and verify it. In a retrieval-based setup, check that the clause actually reached the model's input. If the date is correct but the fee is wrong, inspect table extraction and the association between values and labels. If the model invents an answer to an unlisted question, check instructions, retrieval omissions, and evidence delivery before changing model size. Record whether each answer matches the source, whether its evidence was included, and whether the model acknowledged missing information.
Choose hardware after identifying a recurring document-work bottleneck
First record how long your current setup takes to extract one document, answer the necessary questions, and verify the evidence. If you need to submit the whole document every time, input processing and runtime6 memory may matter. For a workflow that retrieves only a few clauses, retrieval of exceptions and handling of questions absent from the source come first. SSD7 space for storing files is a different requirement from memory used while the model runs.
Keep the extracted text and questions fixed while changing only one setting. Adjust either context length8 or retrieval scope, then compare the answer and waiting stages. Confirm normal operation with a short request, then increase input from a representative page to relevant clauses and the full contract; this reveals where memory or latency becomes a burden. If a scanned number was extracted incorrectly, increasing model size leaves the cause unchanged. Hardware expansion becomes relevant when accurate source text and retrieval still repeatedly hit input or memory limits.
If you choose local execution for privacy, also check where OCR, embeddings, retrieval, and file upload are processed. Run one document end to end and record memory use and errors while the app starts, the PDF is submitted, and follow-up questions are asked. If full contracts are a daily workload and input processing or memory is consistently the bottleneck, consider an upgrade. If you only occasionally inspect a few clauses, the current retrieval workflow may be sufficient. Base the decision on recurring document work, not maximum context length.
Terminology notes
OCR — The process of recognizing characters in images or scanned documents and turning them into text. Table layout and reading order still need the original image to verify.
Back to the textRetrieval-Augmented Generation — A method that retrieves material relevant to a query, adds it to the model input, and generates an answer from that context.
Back to the textPrefill — The stage where an LLM reads the input prompt and computes representations for its tokens. Longer prompts contain more tokens to process.
Back to the textToken decoding — The stage that generates successive output tokens using the input and the response produced so far.
Back to the textAttention — A neural-network operation that calculates relationships between input tokens and combines information from each position into the current representation.
Back to the textRuntime — The software environment that provides facilities needed while a program runs. In local AI, it can also refer to a model execution engine.
Back to the textSSD — A data storage device that uses flash memory and retains data without power.
Back to the textContext window — The token span of input and generated content a model can handle in one request. The supported limit and memory use depend on the model and runtime settings.
Back to the text
Frequently asked questions
- What should you check first in this article?
- A local AI system for PDFs extracts or searches document text to produce answers. If a summary is wrong, first check whether a page of extracted text preserves the source's headings, sentence order, and table values. A larger model or more memory cannot repair corrupted input; compare retrieval methods and hardware only after the document is read correctly.
- How much memory does it need?
- First record how long your current setup takes to extract one document, answer the necessary questions, and verify the evidence. If you need to submit the whole document every time, input processing and runtime memory may matter. For a workflow that retrieves only a few clauses, retrieval of exceptions and handling of questions absent from the source come first. SSD space for storing files is a different requirement from memory used while the model runs.