read first
Guide to building a local RAG: Steps to create an AI that answers your documents
Inserting a document does not immediately provide a good answer.
First check the text extracted from the PDF. Then split it into chunks, retrieve evidence related to the question, and review the model's answer based on those passages. Estimate document volume and concurrent users, and measure latency with the actual evidence length.
Use one question to distinguish ingestion, retrieval, and answering
Suppose you want to answer, “Can an employee who has been here for six months take summer leave?” using the company vacation policy PDF. RAG1 extracts text from the PDF, divides it into searchable passages, and selects passages related to the question for the LLM2. The LLM reads those passages and writes an answer. The system does not reread the entire PDF every time you ask a question.
In your first implementation, display the retrieved passages alongside the answer. If the answer says “Yes” but the passages do not mention the six-month condition, you can see whether the model guessed or retrieval returned the wrong paragraph. If the passages are missing or unrelated, fix extraction or retrieval before changing the answer model. If the passages contain all the necessary conditions but the answer is still wrong, then inspect the prompt or generation model.
To try it yourself, follow LlamaIndex's official local-model example and connect Ollama as the answer model and a Hugging Face embedding as the retriever. First save the vacation policy PDF as data/vacation-policy.pdf. The code below reads text-based PDFs in the data/ folder, creates an index with 700-token3 chunks and 100-token overlap, and sends the same vacation-policy question. Installation and model downloads require network access, but this setup uses Ollama's local server and downloaded embedding weights rather than hosted answer or embedding APIs. The default llama3.1 model files are about 4.9 GB, and inference4 also needs memory for the weights and context, so check available memory as well as disk space. For sensitive documents, prepare the models first, then disconnect the network and confirm the workflow still runs.
The run first prints part of the text extracted from the PDF, followed by the answer and the passages used under “Retrieved evidence.” The wording can vary by model, but the conclusion should match the length-of-service rule in the actual PDF. If the extraction preview is empty or the sentence order is broken, fix OCR or PDF extraction before building the index. If the preview is correct but the evidence is not retrieved, adjust chunking and retrieval settings. If the evidence is correct but the answer differs, check the answer model and instructions.
python -m venv .venv
source .venv/bin/activate
pip install llama-index llama-index-llms-ollama llama-index-embeddings-huggingface llama-index-readers-file
ollama pull llama3.1
mkdir -p datafrom llama_index.core import Settings, SimpleDirectoryReader, VectorStoreIndex
from llama_index.core.node_parser import SentenceSplitter
from llama_index.embeddings.huggingface import HuggingFaceEmbedding
from llama_index.llms.ollama import Ollama
Settings.llm = Ollama(model="llama3.1", request_timeout=360.0)
Settings.embed_model = HuggingFaceEmbedding(model_name="BAAI/bge-m3")
Settings.text_splitter = SentenceSplitter(chunk_size=700, chunk_overlap=100)
documents = SimpleDirectoryReader(
input_dir="data", required_exts=[".pdf"]
).load_data()
if not documents:
raise RuntimeError("No PDF was loaded from data/")
# Check this text against the source PDF before indexing it.
print("Extracted text preview:\n", documents[0].text[:1000])
index = VectorStoreIndex.from_documents(documents)
index.storage_context.persist(persist_dir="storage")
question = "입사 6개월 차 직원도 여름휴가를 쓸 수 있나요?"
response = index.as_query_engine(similarity_top_k=3).query(question)
print("\nAnswer:\n", response)
print("\nRetrieved evidence:")
for source in response.source_nodes:
print("-", source.node.get_content()[:600])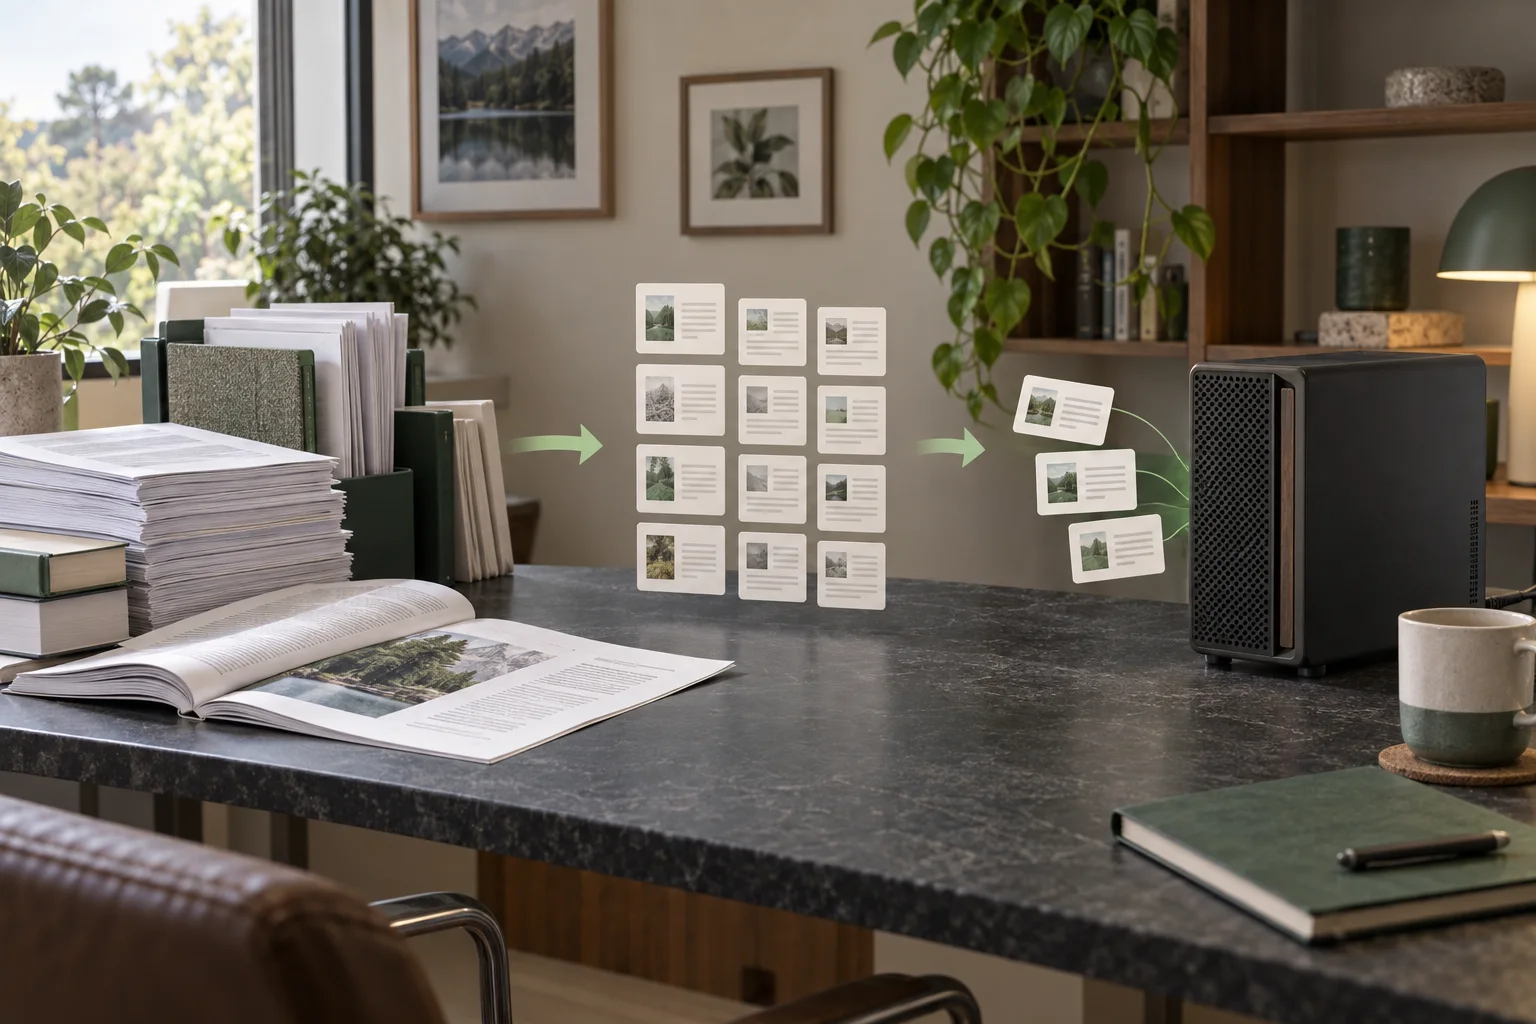
Check for missing PDF text before choosing chunk settings
If the vacation policy uses tables or a two-column PDF layout, extract one page first and compare it with the original. If a condition such as “six months or more” is missing, or table rows are out of order, changing chunk settings will not help because the searchable text is already wrong. Confirm that headings and table entries remain in the correct reading order before continuing.
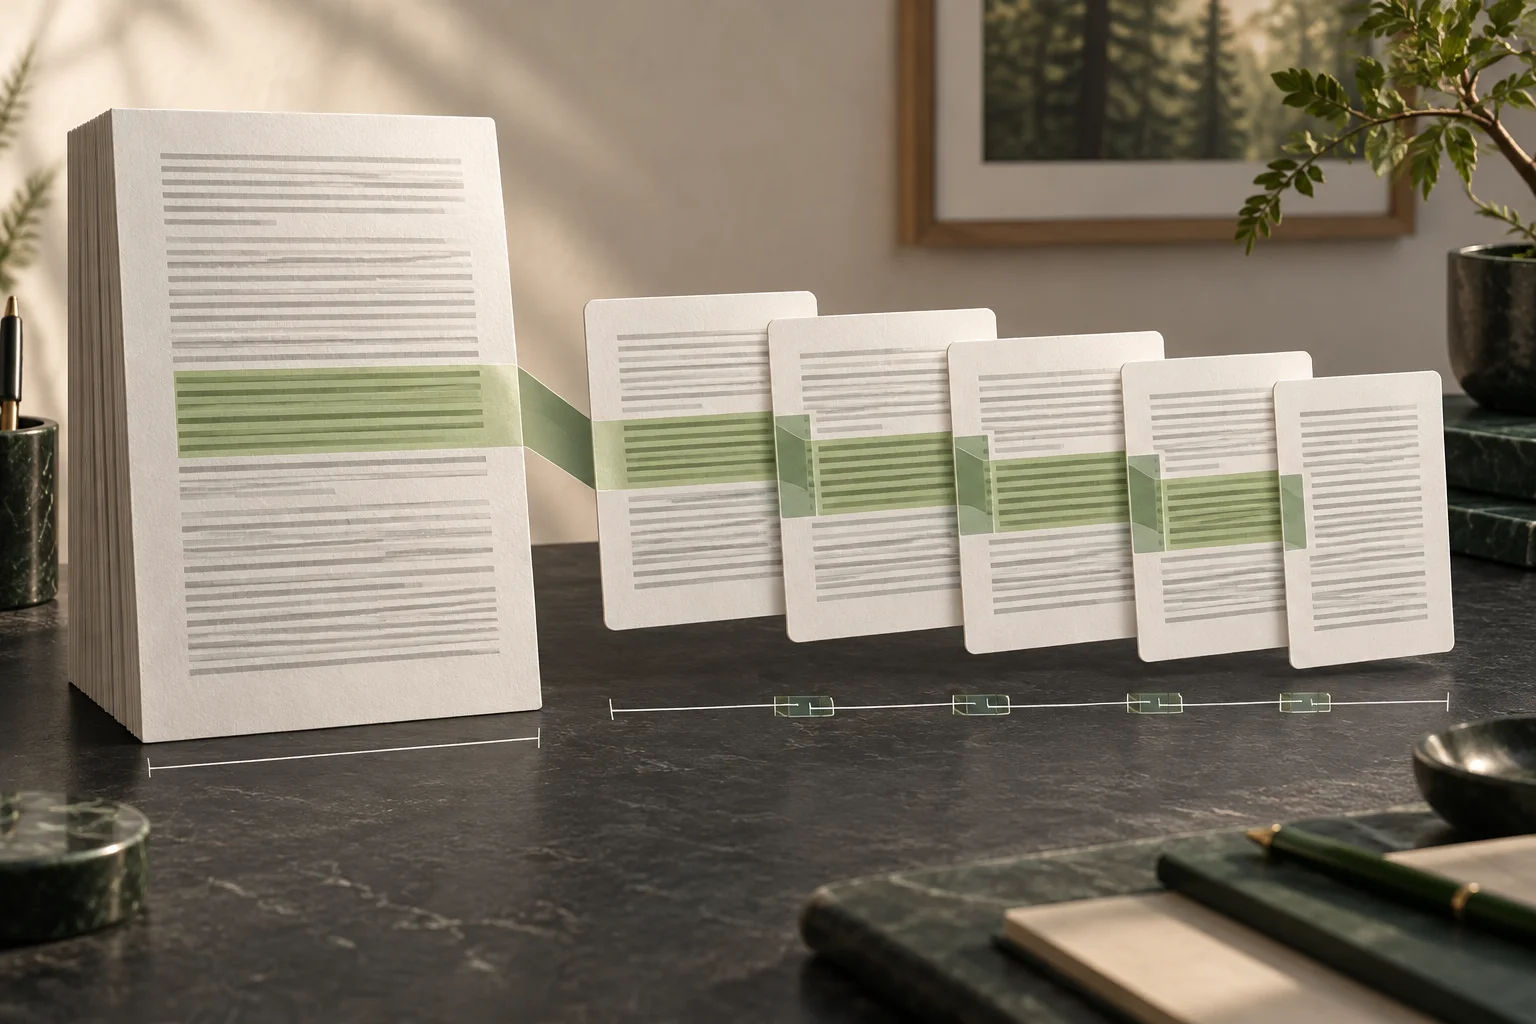
In the example above, the vacation-policy PDF is split into 700-token chunks with 100 tokens of overlap. Each new chunk therefore starts 600 tokens after the previous one began. Overlap helps keep a condition such as “at least six months of service” and its conclusion from being split across separate chunks at a page or paragraph boundary. But larger overlap repeats the same sentences in more chunks, so first inspect the retrieved evidence with this setting and adjust only if needed. The PDF’s token count and resulting chunk count depend on the document, so this guide does not assume a hypothetical document size or calculate vector storage.
Send only the passages needed to answer, and measure each wait separately
You do not need to send the entire policy to the model to answer the vacation question. Check whether the top retrieved passages include conditions such as “summer leave” and “length of service,” then send only the passages needed for the answer. If retrieval is correct but the first token is slow, the model may be taking a long time to read the evidence during prefill5. If the answer streams slowly after the first token, check generation speed separately. If retrieval itself is slow, inspect the index, filters, or storage.
For solo use, first check whether the answer model fits in memory, then measure time to first token6 with the amount of evidence you actually send. When several people ask questions at once, each request adds KV-cache7 use and queueing. In that case, fitting the model in memory is not enough; check how the serving engine handles concurrent requests. Enter document and concurrent-user counts in the calculator to estimate chunk count, storage, and likely hardware bottlenecks.
Use 20 questions to check retrieval and answers together
Create 20 questions about the vacation policy: some with an answer stated directly, some that require finding an exception in a table, and some that the document cannot answer. For each question, write the expected answer and the sentence that must be retrieved, or mark it as “no evidence.” For every run, save the question, extracted text, top retrieved passages, final answer, time to first token, and total response time in one row. This lets you trace a wrong answer back to missing source text, retrieval failure, or the model's interpretation.
If the first results are poor, check source extraction first. Then change only one setting at a time in this order: chunk size or overlap, embeddings, and answer model. Run the same 20 questions again and compare which stage changed. Once the question set passes, increase the document count and number of users to see where the current hardware actually becomes constrained. If you search hundreds or thousands of documents on your own, measure model memory use and evidence-reading time before expanding the vector store.
Terminology notes
Retrieval-Augmented Generation — A method that retrieves material relevant to a query, adds it to the model input, and generates an answer. Search scope and source quality depend on the implementation.
Back to the textLarge language model — A language model trained on large text datasets to process and generate text. Capabilities and supported inputs vary by model.
Back to the textToken — A unit into which a model divides input or output for processing. One token does not equal one character or a fixed duration.
Back to the textInference — The process of using a trained model to compute an output for an input. Here, local inference means running the model on the user’s device.
Back to the textPrefill — The stage where an LLM reads the input prompt and computes representations for its tokens. Longer prompts contain more tokens to process.
Back to the textTime to First Token — The time from sending a request until its first output token arrives. It is separate from the generation rate of later tokens.
Back to the textKV cache — Memory that stores attention keys and values from earlier tokens for reuse during later token generation. Its size depends on context length and batch size.
Back to the text