
Executable programs and extensions
Last updated
What is Darwin-27B-ZTC? Probability-based decisions with 54 GB BF16
It fits tasks with explicit choices where per-option probabilities feed a downstream rule. It is not intended to write free-form explanations or drafts like a generative model.
Darwin-27B-ZTC takes a state and typed questions, then returns a probability distribution over each question's options. noul handles yes/no, choice selects among N options, and score uses an ordered rubric. The model card calls for about 54 GB of BF161 weights, so first confirm that the execution device has room for them.
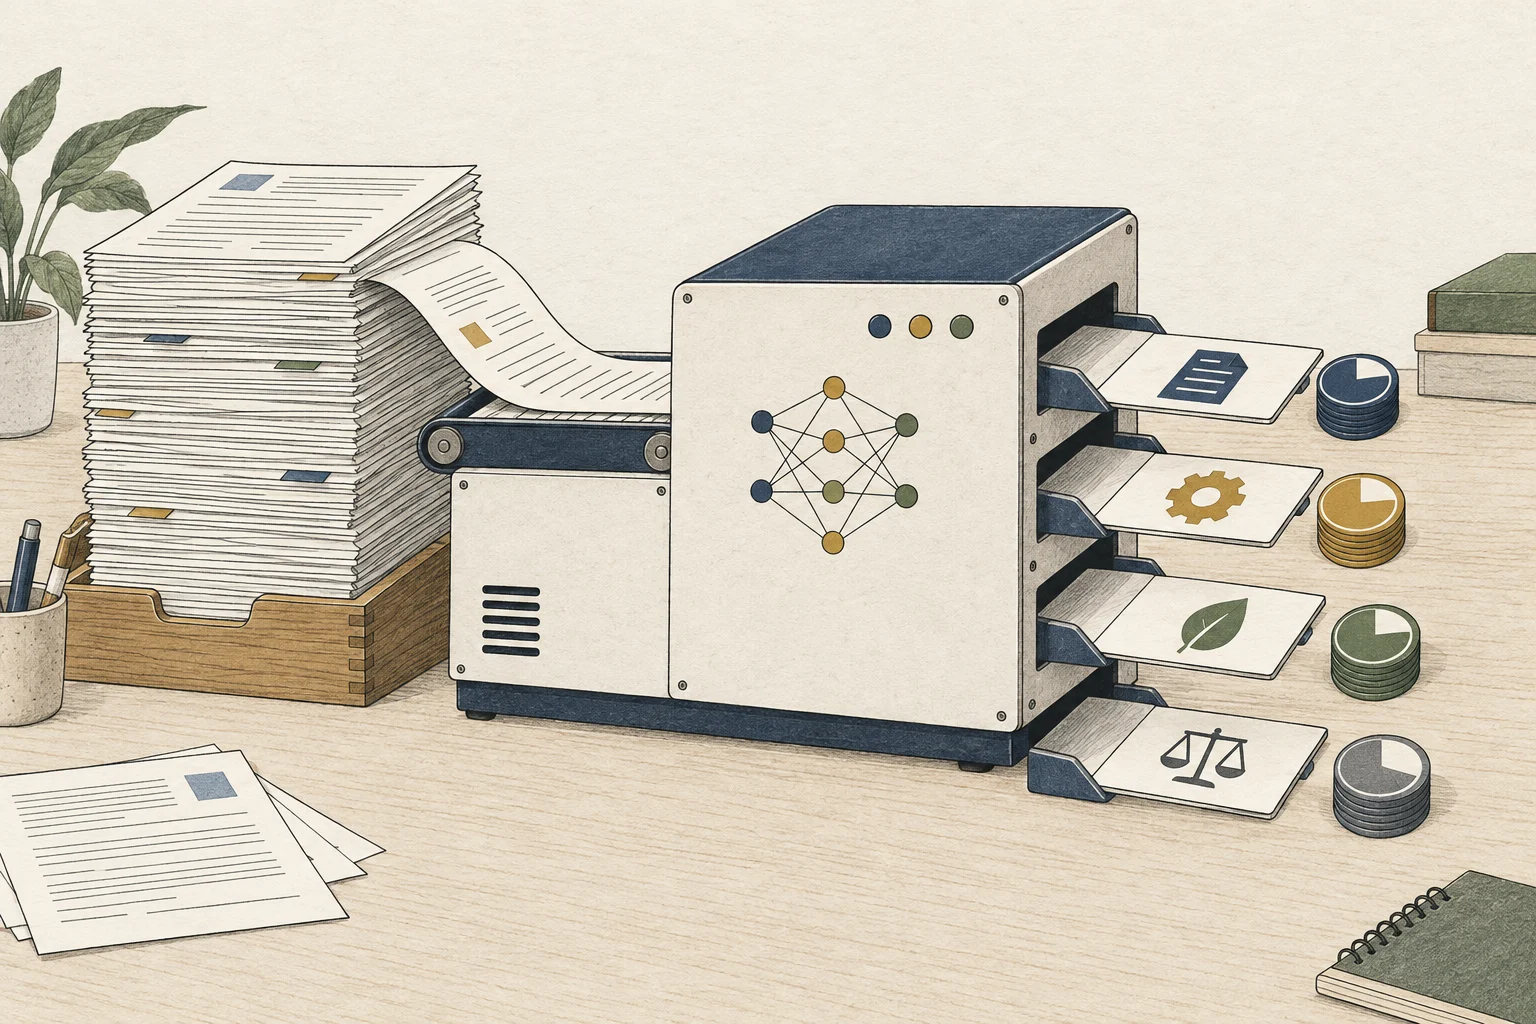
Darwin-27B-ZTC takes a situation or document state with a typed question and returns probabilities for each option. An application can combine that distribution with its own policy or threshold to route for approval, hold, or human review.
For example, a duplicate-charge ticket can be classified as refund, send to billing, or no action. Route low-confidence or sensitive requests to a separate review path under your business policy.
Read option probabilities instead of generated prose
The model card says Darwin processes a state and typed question in one forward pass. It returns a probability distribution by applying softmax to option scores; it generates no tokens2. It is therefore not a model to evaluate with chat-style tok/s or answer length.
The three question types serve different purposes. noul makes a yes/no decision, choice selects one labeled option, and score rates an ordered rubric. Including a description for each option makes the comparison criteria explicit in the input.
Prepare BF16 memory and the Python environment
The model card lists about 54 GB of GPU3 memory for BF16 weights. That figure covers weights, so leave additional room for the operating system, CUDA4 context, and input length. If the device cannot provide that capacity, do not assume this example will run unchanged; first check the model card for an official quantized or distributed option.
The model card's local example downloads a Hugging Face snapshot and imports autojev.model.DecisionModel. Listed dependencies are PyTorch5, Transformers with Qwen3.5 support, safetensors, and Pillow. The decision code and weights are both required, including readout.safetensors and decision_config.json alongside the backbone files.
pip install torch transformers safetensors pillow huggingface_hub
Build a state and typed question, then inspect probabilities
The card example combines state and question in one row and passes it to model.predict([row]). A choice question includes its type, instructions, and descriptions by option. Save the code as decide.py and run python decide.py; verify option names and probability indexes with a fixed case before wiring it into a service.
import sys
from huggingface_hub import snapshot_download

path = snapshot_download("FINAL-Bench/Darwin-27B-ZTC")
sys.path.insert(0, path)
from autojev.model import DecisionModel
model = DecisionModel(checkpoint=path)

row = {
    "state": {"ticket": "Customer was charged twice for the same order."},
    "question": {
        "type": "choice",
        "instructions": "What should support do?",
        "criteria": {
            "refund": "Refund the duplicate charge.",
            "escalate": "Send to billing.",
            "close": "No action.",
        },
    },
}
probabilities = model.predict([row])[0]
for label, probability in zip(row["question"]["criteria"], probabilities):
    print(label, float(probability))
The example below follows the model card's duplicate-charge classification. No output probability values are stated here because they depend on the hardware and package version used. Check that the option probabilities form a distribution near 1 and preserve input order before connecting them to application policy.
Do not treat probabilities as approval by themselves
On the model card's Typed Decisions evaluation, the test split contains 400 cases and 2,000 decisions, with reported overall accuracy of 0.743. This is a result on that evaluation set, not a guarantee for your business data. The card also describes the difference between two runs, 0.741 and 0.743 accuracy, as run-to-run variation from request batching.
Compare representative cases with real labels to evaluate classification errors and probability calibration. If BF16 memory is unavailable or the task needs free-form explanations, another decision or generative path may fit better.
Terminology notes
BF16 — A 16-bit floating-point format for model values. Its exponent has the same width as FP32, giving it a similarly wide value range.
Back to the textToken — A unit into which a model divides input or output for processing.
Back to the textGPU — A processor designed to handle many calculations in parallel. It performs model computations during AI inference.
Back to the textCUDA — A software platform for general-purpose computing on NVIDIA GPUs.
Back to the textPyTorch — A software framework for building and running AI models. Check the compatible PyTorch version and hardware support along with the model.
Back to the text
Frequently asked questions
- What should you check first in this article?
- Darwin-27B-ZTC takes a state and typed questions, then returns a probability distribution over each question's options. `noul` handles yes/no, `choice` selects among N options, and `score` uses an ordered rubric. The model card calls for about 54 GB of BF16 weights, so first confirm that the execution device has room for them.
- How much memory does it need?
- The model card lists about 54 GB of GPU memory for BF16 weights. That figure covers weights, so leave additional room for the operating system, CUDA context, and input length. If the device cannot provide that capacity, do not assume this example will run unchanged; first check the model card for an official quantized or distributed option.
- Where can you check the conditions and sources?
- The model card lists about 54 GB of GPU memory for BF16 weights. That figure covers weights, so leave additional room for the operating system, CUDA context, and input length. If the device cannot provide that capacity, do not assume this example will run unchanged; first check the model card for an official quantized or distributed option.