
Executable programs and extensions
Last updated
Laya-MLX: a decision model that answers in 13 ms on a Mac
It computes probabilities instead of generating text
Laya-MLX is a Python package that runs a 421-million-parameter decision model on MLX1. Instead of generating text it returns a probability for each option in one pass. One short question takes about 13 ms, and batching 50 questions reaches 146.8 per second.
It computes probabilities instead of writing an answer
Laya-MLX does not produce sentences. It takes a state and a question together and returns a probability for each named option, which is why output tokens2 stay at zero.
The structure splits into an encoder and decision heads. A bidirectional encoder reads state and question together and the heads compute the probabilities. With no token-by-token loop the latency stays short.
Asking a generative model to choose means getting a sentence back and parsing it. A broken format adds a retry and the latency that comes with it. Receiving the probability directly removes the parsing step.
The models come in two sizes, 421 million and 322 million parameters. Compared with running a generative model on the same Mac, memory use stays under a gigabyte.
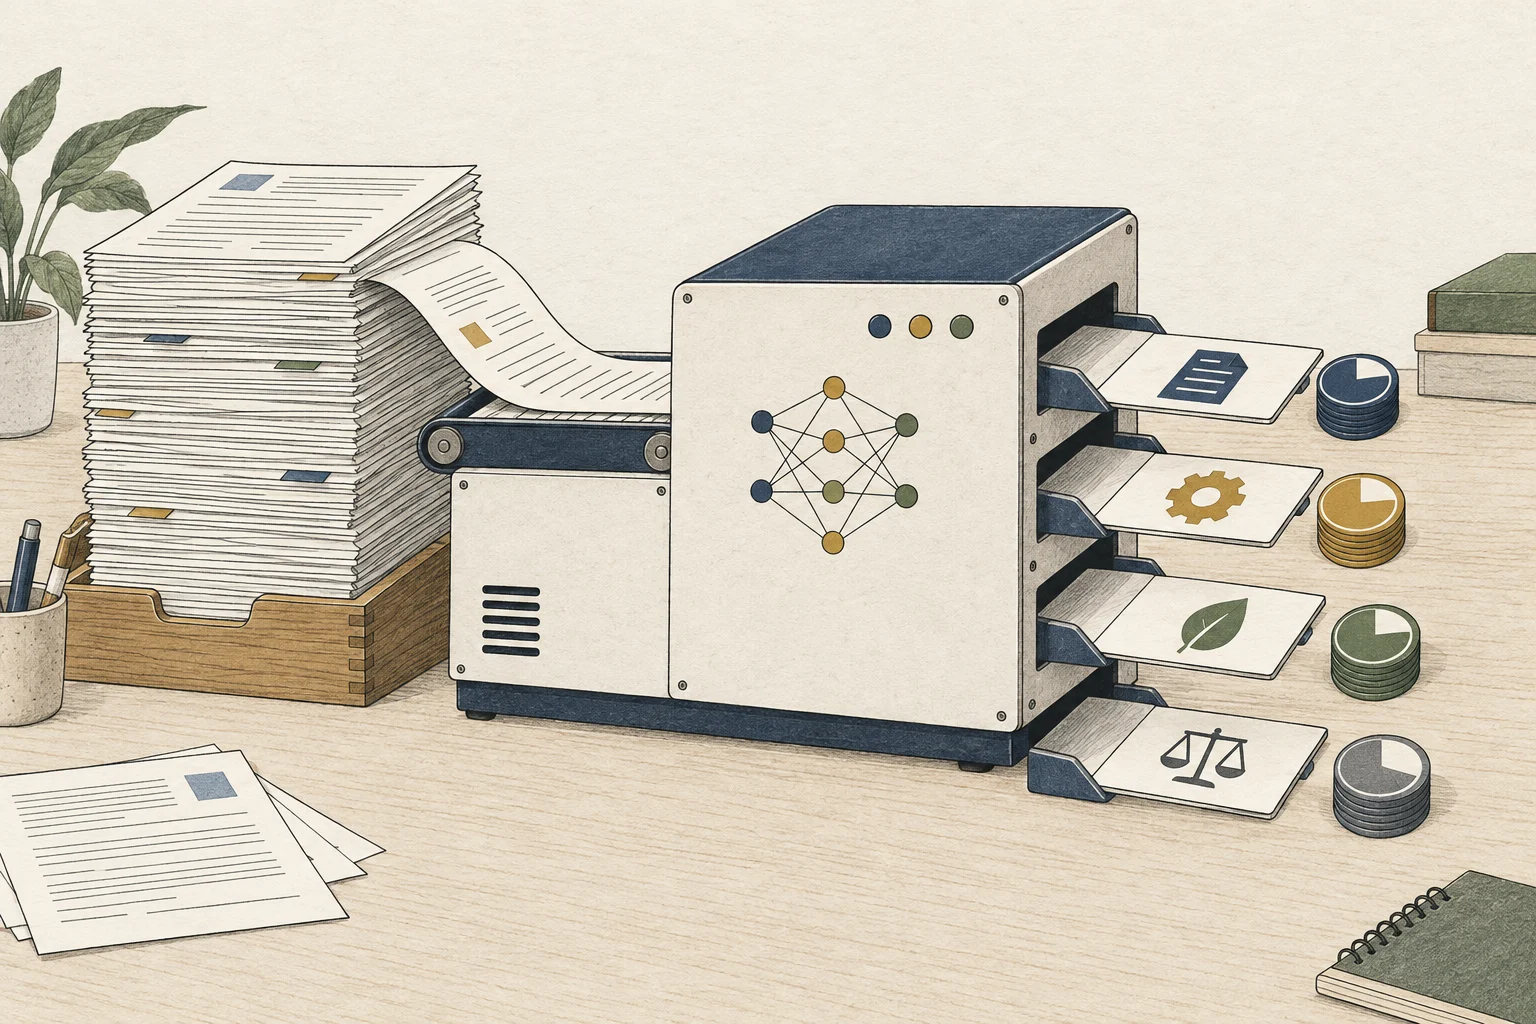
There are three kinds of question: choice, score and true or false
A choice question returns a probability for each named option. A score question returns probabilities over ordered levels and their expected score, and a true/false question returns a single probability.
| Type | Returns | Where it fits |
|---|---|---|
| Choice | A probability per option | Classification and routing |
| Score | Level probabilities and expected score | Quality rating |
| True or false | A single P(true) | Checking a condition |
It does not fit writing prose or multi-step reasoning. It is for choosing among named options or rating on fixed levels.
Install it and get a first decision
Install the package, load a model and pass a state and a question. The example below routes a support message into one of three departments.
pip install laya-mlxThe first load downloads the checkpoint3, and after that inference4 stays local. It needs Python 3.11 or later and macOS 14 or later.
import laya_mlx as laya

agent = laya.load("aac6fef/laya-mlx")
result = agent.predict(
    "I was billed twice. Please refund the duplicate.",
    {"department": {
        "type": "choice",
        "instructions": "Who should handle this?",
        "criteria": ["billing", "technical", "sales"],
    }},
)
print(result["answers"]["department"])
It can also run on the CPU5 instead of the GPU6. Changing only the backend moves the same code between the two.
Pick one of three checkpoints
If you only handle English, the 421M model is enough; with mixed languages the multilingual checkpoint is faster. Their context limits differ, so check that number before passing long instructions.
Scroll sideways to compare all columns.
| Checkpoint | Parameters | Context limit | Purpose |
|---|---|---|---|
| Laya | 421 million | 512 tokens | English input |
| Multilingual | 322 million | 1,024 tokens | Multilingual input |
| Typed decisions | 421 million | 1,024 tokens | Porting upstream workflows |
Pre-converted FP167 checkpoints are published, so you can load one directly instead of converting the original weights yourself.
The latency and throughput measured on a Mac
The measurement ran on an M3 Max with a 40-core GPU and 128 GB of memory. The timing includes prompt8 preparation, tokenization, synchronized inference, calibration and formatting, and excludes model loading.
| Metric | Laya 421M | Multilingual 322M |
|---|---|---|
| One short question, P50 | 13.42ms | 7.39ms |
| One short question, P95 | 13.92ms | 7.79ms |
| 50-question throughput | 146.8 per second | 395.0 per second |
| Peak allocation | 943.6MiB | 687.6MiB |
The numbers move with question length and count. The table measures one short question and a batch of 50, so longer instructions add latency.
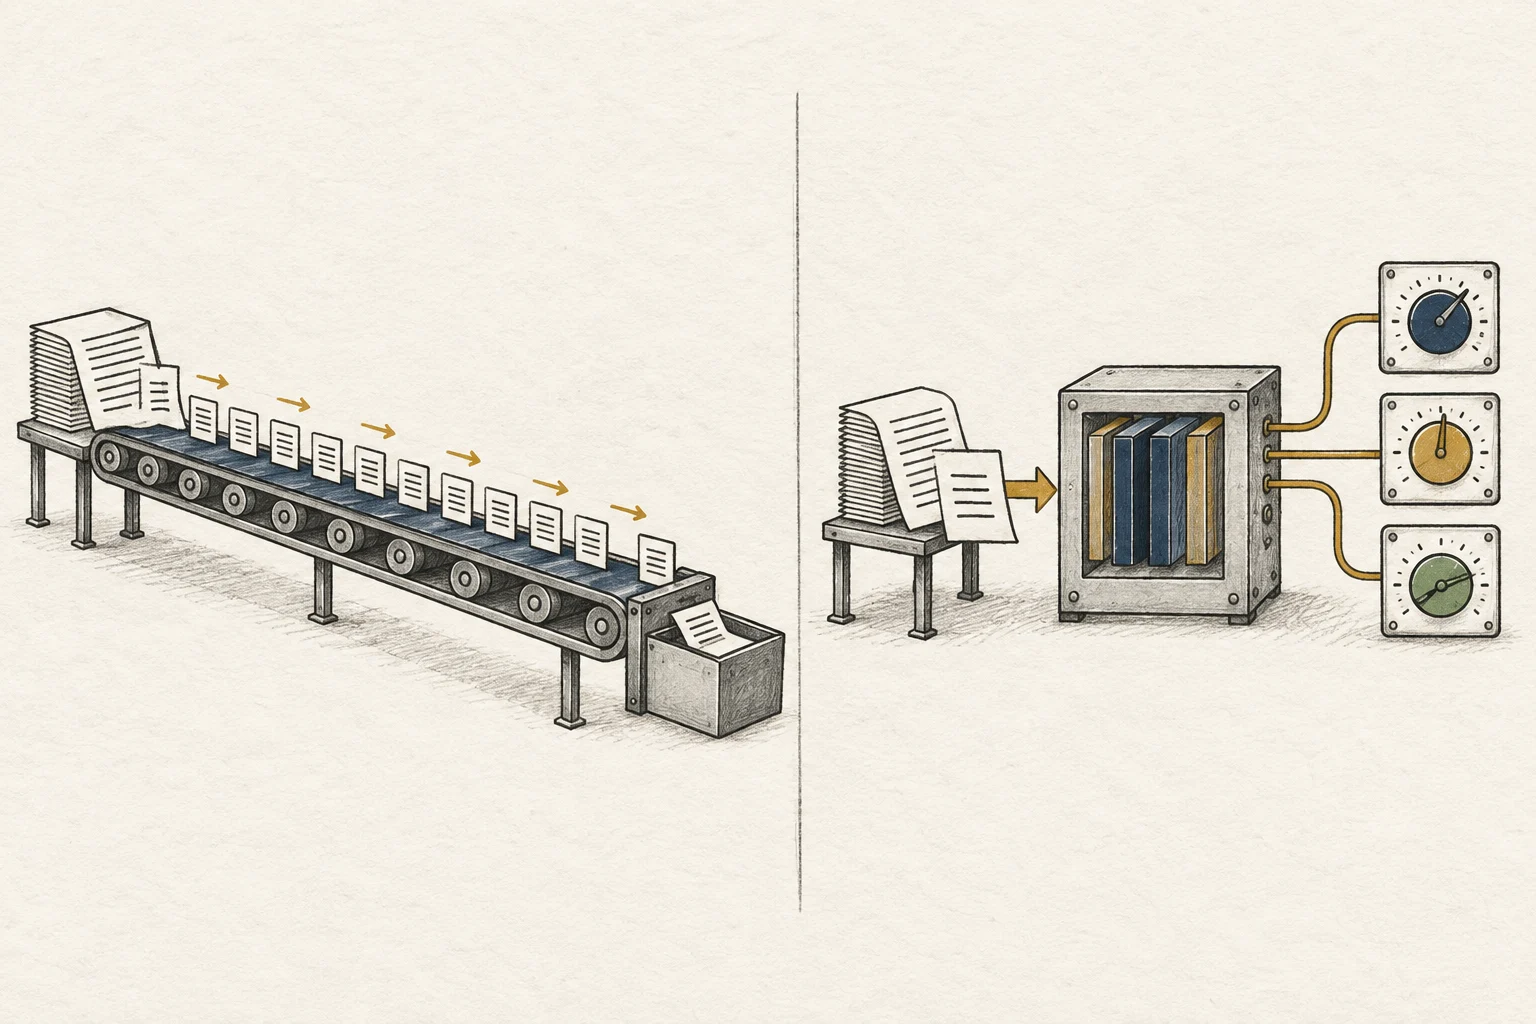
It first checked that the answers match
The MLX port was checked against the original on 63 validation questions. All 63 matched in both FP329 and FP16, so all 378 comparisons passed.
Repeating the same call 100 times returned finite, identical results without memory growth. That holds for those fixtures, not for every possible question.
The game demo serves the same check. A Snake run handled 2,400 moves with two safety interventions and no deaths, about 6.5% faster than its eager control.
Fidelity came before speed. Where a probability is used, a one-point difference changes the decision, so matching the original is the starting point.
Attach it to an app or a server
Entry points for an HTTP server and an MCP10 server ship with the package. Calling it from an app or exposing it as an agent tool needs no extra code.
pip install 'laya-mlx[serve]'
laya-mlx-serve
Extras for frameworks such as LangChain and LlamaIndex ship separately, so you can swap only the decision step in a pipeline11 you already run.
When sending many questions at once, tune the batch size12. The default is 16, and the 50-question throughput13 above used a batch of 64.
Remember that this is a port
This package is an independent MLX port, not an official release from the original authors. It keeps the original weights, question formatting, calibration and output schema, but its support surface differs.
CUDA14 and ONNX execution and training are not included. Training stays with the upstream project; this package covers inference and conversion.
The repository records which upstream revision it follows. Checking that record against the upstream documentation shows which features are still missing.
The measurement ran on macOS 27.2, and older versions cannot be assumed to match. Measure the latency yourself with a short question before relying on it.
Terminology notes
MLX — Apple’s machine-learning framework, which runs models using memory shared by the CPU and GPU on Apple Silicon.
Back to the textToken — A unit into which a model divides input or output for processing.
Back to the textCheckpoint — A file containing saved model weights and related state. Versions or tasks in one model family may use different checkpoints.
Back to the textInference — The process of using a trained model to compute an output for an input. Here, local inference means running the model on the user’s device.
Back to the textCPU — The central processor that runs the operating system and general-purpose instructions; in AI workloads it also handles tasks such as preprocessing and data movement.
Back to the textGPU — A processor designed to handle many calculations in parallel. It performs model computations during AI inference.
Back to the textFP16 — A 16-bit floating-point format. It uses the same bit width as BF16 but allocates bits differently between exponent and significand.
Back to the textPrompt — The input text sent to a model. For generative models it describes the desired result and strongly shapes the output.
Back to the textFP32 — A 32-bit floating-point format. It uses more memory per value than BF16 and can represent values more precisely.
Back to the textMCP — A protocol for connecting clients to tools and data sources a model may use. Connectivity and permission to execute a particular tool must still be configured separately.
Back to the textPipeline — A sequence of processing stages from input to output. Different models or tools may be used at each stage.
Back to the textBatch size — The number of inputs or requests processed together in one batch.
Back to the textThroughput — The amount of work processed or generated over time. Comparisons need the unit, such as tokens per second or requests per second.
Back to the textCUDA — A software platform for general-purpose computing on NVIDIA GPUs.
Back to the text
Frequently asked questions
- What should you check first in this article?
- Laya-MLX is a Python package that runs a 421-million-parameter decision model on MLX. Instead of generating text it returns a probability for each option in one pass. One short question takes about 13 ms, and batching 50 questions reaches 146.8 per second.
- How much memory does it need?
- The models come in two sizes, 421 million and 322 million parameters. Compared with running a generative model on the same Mac, memory use stays under a gigabyte.