
read first
Last updated
RTX Spark laptops: how do they differ from DGX Spark and MacBook Pro?
Choose what matters first: model compatibility or portability.
RTX Spark laptops are a new Windows on Arm platform with CUDA-capable Blackwell GPUs and shared CPU/GPU memory. DGX Spark is a Linux desktop AI system, while MacBook Pro uses macOS and the Apple Silicon ecosystem, including MLX1 and Core ML2. Compare them by GPU-addressable memory on the exact SKU and by the apps and model recipes you need.
RTX Spark is a Windows on Arm platform used by several laptop manufacturers. Its Blackwell RTX GPU3 and Grace CPU4 share unified memory5. Check GPU-accessible capacity on your chosen SKU alongside memory used by Windows, apps, and the model runtime6. Microsoft Surface configurations
DGX Spark, by comparison, is a desktop system with GB10, 128GB coherent unified memory, and DGX OS. MacBook Pro runs macOS and offers Apple Silicon unified-memory configurations with apps such as MLX and Core ML. Even when memory figures look similar, OS, app compatibility, runtime recipes, and thermal design differ. NVIDIA DGX Spark · Apple MacBook Pro specifications
RTX Spark laptops and their top specifications
RTX Spark laptops are a platform with Windows on Arm, a Grace CPU, a Blackwell RTX GPU, and unified memory. Microsoft's maximum Surface Laptop Ultra configuration has a 15-inch display, up to 20 Grace CPU cores, up to 6,144 Blackwell GPU cores, and up to 128 GB of unified memory.
The maximum AI performance figure is a theoretical value using FP4 and sparsity. Measure actual processing time with the runtime, model, and input you plan to use. Surface announcement and SKU specifications
The GPU can use less than the full 128 GB of system unified memory. Windows, the browser, IDE, and image or video frames7 share the same memory pool with model weights and the KV cache8.
Distinguish the total memory in a product SKU from GPU-addressable memory, and check the model recipe's minimum memory and context allocation as well.
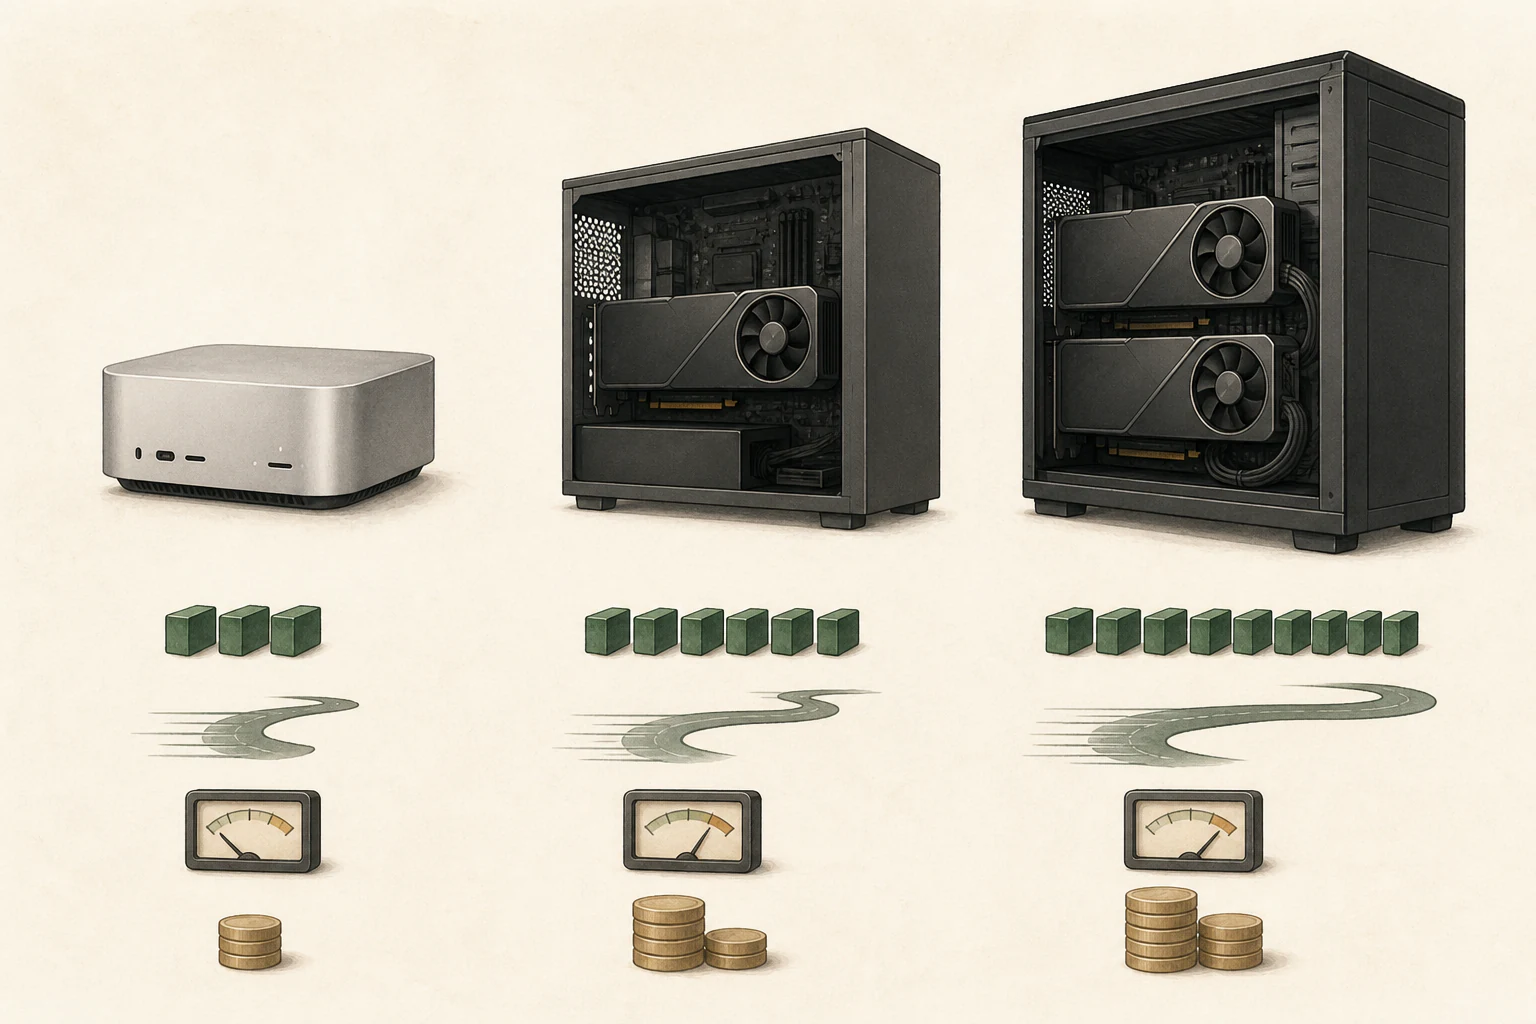
Compare DGX Spark and MacBook Pro
For these three platforms, OS and runtime compatibility often matter more than the shared ability to run local inference9. RTX Spark is a candidate when you want CUDA10 and Windows creative apps on a laptop. DGX Spark suits a desktop system centered on Linux and NVIDIA serving recipes. If your workflow uses macOS apps and MLX or Core ML, start with MacBook Pro configurations.
| Device | OS and form factor | Memory and AI software |
|---|---|---|
| RTX Spark laptop | Windows on Arm · portable | Unified memory varies by Surface SKU; GPU-addressable capacity is lower |
| DGX Spark | DGX OS/Linux · desktop | GB10 and 128GB coherent unified memory; NVIDIA DGX/vLLM workflows |
| MacBook Pro | macOS · laptop | Apple Silicon unified memory varies by SKU; MLX and Core ML ecosystem |
MacBook Pro memory options vary by chip configuration. The NVIDIA and Apple figures describe each manufacturer’s platform, not comparative performance.
Apple lists MacBook Pro unified memory by chip and GPU SKU. Its 2026 M5 Pro/M5 Max specifications list up to 128GB for an M5 Max with a 40-core GPU and up to 64GB for M5 Pro configurations. For Mac, check the model formats supported by apps such as MLX or Core ML; for RTX Spark, check the Windows on Arm and CUDA path. Apple MacBook Pro specifications
Check Windows on Arm and app versions
Windows has Arm64 apps and x86 apps that run through Prism. NVIDIA and Microsoft announced CUDA and developer tool support for RTX Spark. Check each product's documentation to see whether your packages, plugins, and containers support the Windows on Arm CUDA path.
An x86 command-line app running does not establish that CUDA extensions or drivers will work the same way. Windows development environment on RTX Spark
RTX Spark laptop availability on October 16, 2026, may vary by region and SKU. Use the announced manufacturer list to identify candidates, then make a final choice from the exact product page’s memory, storage, display and thermal design, and Arm app compatibility. NVIDIA COMPUTEX platform announcement

Before purchase: check the exact SKU and app support
Before buying, note the checkpoint11 size, required context, and whether you need image or video input, then compare them with GPU-addressable memory on the candidate SKU. Check Windows Arm64 and CUDA support in the model and app documentation. Test a real request after receiving the device, or earlier if you can use a demo unit.
The published Surface Laptop Ultra specifications are an example of the highest confirmed configuration among announced RTX Spark laptops. Other RTX Spark models may use the same platform but differ in memory options, display, battery, and cooling.
Compare memory and AI workload performance using the exact order SKU and manufacturer specifications of the product you plan to buy.
After purchase: test with your model and workload
NVIDIA tested Bolt IQ2_XXS and LiLiCorr on a 128 GB Surface Laptop Ultra using Windows 11 ARM and llama.cpp. The AIPerf SPEED-Bench-Coding result was 83.99 TPS, and AA-AgentPerf Local replay time in the same test was 600.80 seconds.
This is an example of an actual model and runtime combination among published RTX Spark laptop results. Compare it separately from measurements on DGX Spark or MacBook Pro. Bolt test conditions
After receiving the device, prepare the checkpoint you plan to use and repeat a short request to separate first-load time from subsequent responses. Then open your usual apps and increase context, image resolution, or video frames while recording GPU memory, completion time, fan noise, and power state. For a useful MacBook Pro comparison, match model, quantization12, context, and request.
Terminology notes
MLX — Apple’s machine-learning framework, which runs models using memory shared by the CPU and GPU on Apple Silicon.
Back to the textCore ML — Apple’s framework for running machine-learning models on its devices.
Back to the textGPU — A processor designed to handle many calculations in parallel. It performs model computations during AI inference.
Back to the textCPU — The central processor that runs the operating system and general-purpose instructions; in AI workloads it also handles tasks such as preprocessing and data movement.
Back to the textUnified memory — An architecture where the CPU and GPU share one physical memory pool.
Back to the textRuntime — The software environment that provides facilities needed while a program runs. In local AI, it can also refer to a model execution engine.
Back to the textFrame — A single image that makes up part of a video.
Back to the textKV cache — Memory that stores attention keys and values from earlier tokens for reuse during later token generation. Its size depends on context length and batch size.
Back to the textInference — The process of using a trained model to compute an output for an input. Here, local inference means running the model on the user’s device.
Back to the textCUDA — A software platform for general-purpose computing on NVIDIA GPUs.
Back to the textCheckpoint — A file containing saved model weights and related state. Versions or tasks in one model family may use different checkpoints.
Back to the textQuantization — A way to represent model weights or values with fewer bits, reducing storage and memory use. The coarser representation can also affect accuracy.
Back to the text
Frequently asked questions
- What should you check first in this article?
- RTX Spark laptops are a new Windows on Arm platform with CUDA-capable Blackwell GPUs and shared CPU/GPU memory. DGX Spark is a Linux desktop AI system, while MacBook Pro uses macOS and the Apple Silicon ecosystem, including MLX and Core ML. Compare them by GPU-addressable memory on the exact SKU and by the apps and model recipes you need.
- How much memory does it need?
- RTX Spark laptops are a platform with Windows on Arm, a Grace CPU, a Blackwell RTX GPU, and unified memory. Microsoft's maximum Surface Laptop Ultra configuration has a 15-inch display, up to 20 Grace CPU cores, up to 6,144 Blackwell GPU cores, and up to 128 GB of unified memory.