
Purchases and Costs
Last updated
Orca Connect: attach your own GPU to Claude Code
One outbound connection, spillover off by default
Orca Connect publishes your home GPU1 into the OrcaRouter catalogue as local/your-rig/your-model. It opens one outbound connection with no port forwarding, and a local-only key blocks hosted billing. Prompts2 still pass through the router, and the free tier is a current condition, not a promise.
What actually changes
Run the connector on your machine and it finds the local runtimes, then lets you pick which models to share. They appear in the catalogue as local/your-rig/your-model.
Callers keep using the key and endpoint they already have; from a laptop or a phone the request still reaches your machine through the router.
There is no port forwarding, no tunnel to configure and no new firewall rule, and nothing is exposed until you pick a model to share.
The connector only shares models already loaded in that machine's memory, so a 24 GB box lists whatever fits inside 24 GB.
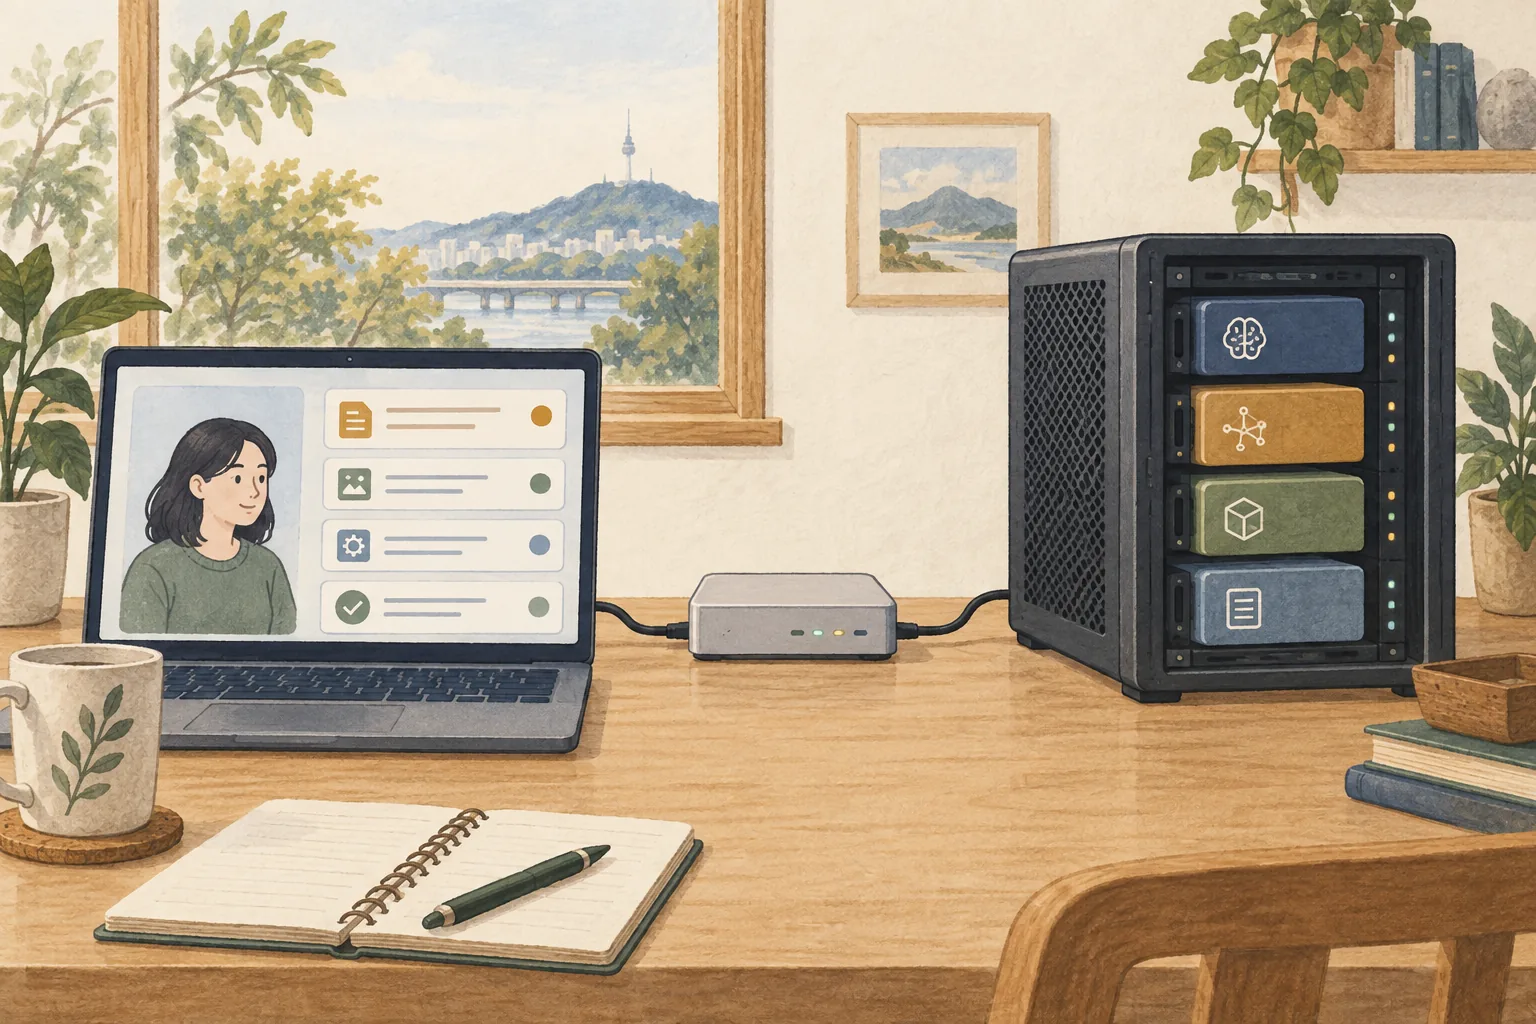
Spillover starts switched off
With spillover on, a hosted model answers only for the reasons you allowed, only the model you picked, and only within the monthly cap. With it off, none of that happens.
Response headers record where the work ran: X-Orca-Billed: false for your hardware, and a reason plus expected cost when a hosted model took over.
| Situation | Response | Billing |
|---|---|---|
| Your machine answered | X-Orca-Billed: false | KRW 0 |
| Machine off, spillover off | 503 local_connector:unavailable | None |
| Machine off, spillover on | X-Orca-Spillover-Reason: rig_offline | Hosted rate |
| Monthly cap reached | Refusal | None |
Point a coding agent at your machine
Running orca-connect claude starts Claude Code against your model for that session only, leaving the agent's own configuration alone.
Swap claude for codex, opencode, gemini, qwen, kimi, copilot, aider, goose or pi and the matching CLI3 sees your model the same way.
| Command | CLI it launches | When to use |
|---|---|---|
| orca-connect claude | Claude Code | You already use Claude Code |
| orca-connect codex | Codex CLI | Long terminal sessions |
| orca-connect aider | Aider | File-by-file edits |
| orca-connect goose | Goose | Tool-heavy workflows |
Prompts still cross the router
A key marked local-only keeps inference4 off hosted models and blocks billing, but the request itself still travels through OrcaRouter.
The distinction matters because where inference runs and where data travels are different questions; if you handle page content or internal documents, settle this first.
Install and share once
Install the connector and approve the machine once in a browser; a headless server approves with a code instead.
orca-connect status lists the runtimes it found, and the console is where you pick which to share; the tray or orca-connect expose handles the first pick.
orca-connect status
orca-connect expose
Where it falls short
It is a commercial service. It is free today, but pricing and terms can change, so check them before putting it into a workflow.
The machine has to be awake with a live connection; sleep or a reboot makes outside calls fail.
For same-room use a plain LAN server is faster and simpler, so this connector is not a LAN replacement; it pays off when you call from outside.
The licence of a shared model is your responsibility; check the commercial terms on its model card.
Terminology notes
GPU — A processor designed to handle many calculations in parallel. It performs model computations during AI inference.
Back to the textPrompt — The input text sent to a model. For generative models it describes the desired result and strongly shapes the output.
Back to the textCLI — Short for Command-Line Interface: operating a program by entering commands in a terminal.
Back to the textInference — The process of using a trained model to compute an output for an input. Here, local inference means running the model on the user’s device.
Back to the text
Frequently asked questions
- What should you check first in this article?
- Orca Connect publishes your home GPU into the OrcaRouter catalogue as local/your-rig/your-model. It opens one outbound connection with no port forwarding, and a local-only key blocks hosted billing. Prompts still pass through the router, and the free tier is a current condition, not a promise.
- How much memory does it need?
- The connector only shares models already loaded in that machine's memory, so a 24 GB box lists whatever fits inside 24 GB.
- When is it better not to choose this?
- For same-room use a plain LAN server is faster and simpler, so this connector is not a LAN replacement; it pays off when you call from outside.
- Where can you check the conditions and sources?
- The licence of a shared model is your responsibility; check the commercial terms on its model card.