
Executable programs and extensions
Last updated
Local Jev-like decisions with Qwen: SemIf, Simple Jev and openjev-sglang
Qwen-based Jev-style projects differ in logits, API experiments, and server throughput
Qwen-based Jev-style projects take documents and choices and return classifications and candidate scores. SemIf targets 4B personal-machine experiments, Simple Jev demonstrates a 0.8B CPU1 API2, and openjev-sglang focuses on 35B parallel server processing. Choose a starting point for your hardware and decision task.
Local projects for Jev-style decisions start from different goals: reading scores, demonstrating an API, dedicated training, or server throughput3. Identify the model and runtime4 first, then evaluate choice accuracy and latency separately on data relevant to your use.
Read candidate-token scores to produce decisions
Define department choices such as billing, access, and security, then provide an inquiry. Reading the model's next-position logits and applying softmax yields relative probabilities within that choice set. The model need not generate prose or lengthy JSON; server code constructs the response. Still verify tokenization of each label, semantic distinctions, and whether confidence matches actual accuracy.
For illustration, logits of 2, 1, and 0 yield softmax values of about 66.5%, 24.5%, and 9.0%. These are normalized scores within the three choices, not a guarantee that the first choice has that probability of being correct.
- RTX 3090 24GB memory, speed and price
- Prefill vs decode: should you look at TTFT or tok/s?
- GGUF vs MLX: which model format should you download?
- Run Jev-Style Local Decision Models on Mac, RTX 3090, and Servers
- Jev-Omni: multimodal decisions on local GPUs
- What is Jev? A System One model that decides instead of writing
SemIf is aimed at 4B comparisons on personal hardware
SemIf continues the earlier renamed OpenJev repository and reads candidate logits from Qwen3.5-4B. It can reuse a shared-document prefill5 and evaluate question branches in parallel; CUDA6 experiments on RTX 3090 and an Apple silicon MLX7 backend are also published. It is a closer starting point than a server-scale setup for reproducible personal-hardware comparisons.
Because choices from the faster shared path may differ from basic scoring, record agreement alongside latency. Fix the inquiry and model revision and compare fresh and shared paths on the same evaluation data. Agreement between paths does not establish correctness; count errors against human-labeled references.
Simple Jev is an example for learning the API on CPU
Rather than retraining a classification head, Simple Jev reads logits from an open model through Transformers and PyTorch8. Its Qwen3.5-0.8B CPU example lets you inspect request and response structure without a high-end GPU9. Start with a small choice set and verify the output shape.
A successful request confirms the API flow, not decision accuracy for your business. You can also check whether compatible routes /v1/classifier and /v1/systemone call the same implementation. Separate interface compatibility from quality, collect semantic errors, and then decide whether a 4B model is needed.
Choose a project by its implementation path
Simple Jev is a small entry point for learning a decision API on CPU; SemIf explores Qwen 4B-class models on personal hardware. openjev-sglang targets parallel execution on B200 servers, not the same setup as a desktop tutorial.
A candidate-scoring library and a /v1/systemone server request are different execution methods. Keep the ticket and action names fixed for comparison, but adapt input fields and option order to each project’s example.
openjev-sglang is a parallel-serving baseline for B200
openjev-sglang serves the Qwen3.6-35B-A3B NVFP410 checkpoint11 through SGLang and uses radix cache and parallel requests. Its published baseline uses one B200, so it should not be read as an installation recipe for a personal GPU. The relevant design is reuse of a shared prefix across questions.
The published throughput for 64 questions depends on accelerator, input length, and concurrency. Throughput differs from one request's latency. For example, the hypothetical completion of 64 questions in four seconds would mean 16 per second, not that each request took 1/16 second. This is an illustrative assumption, not a restatement of the B200 measurement.
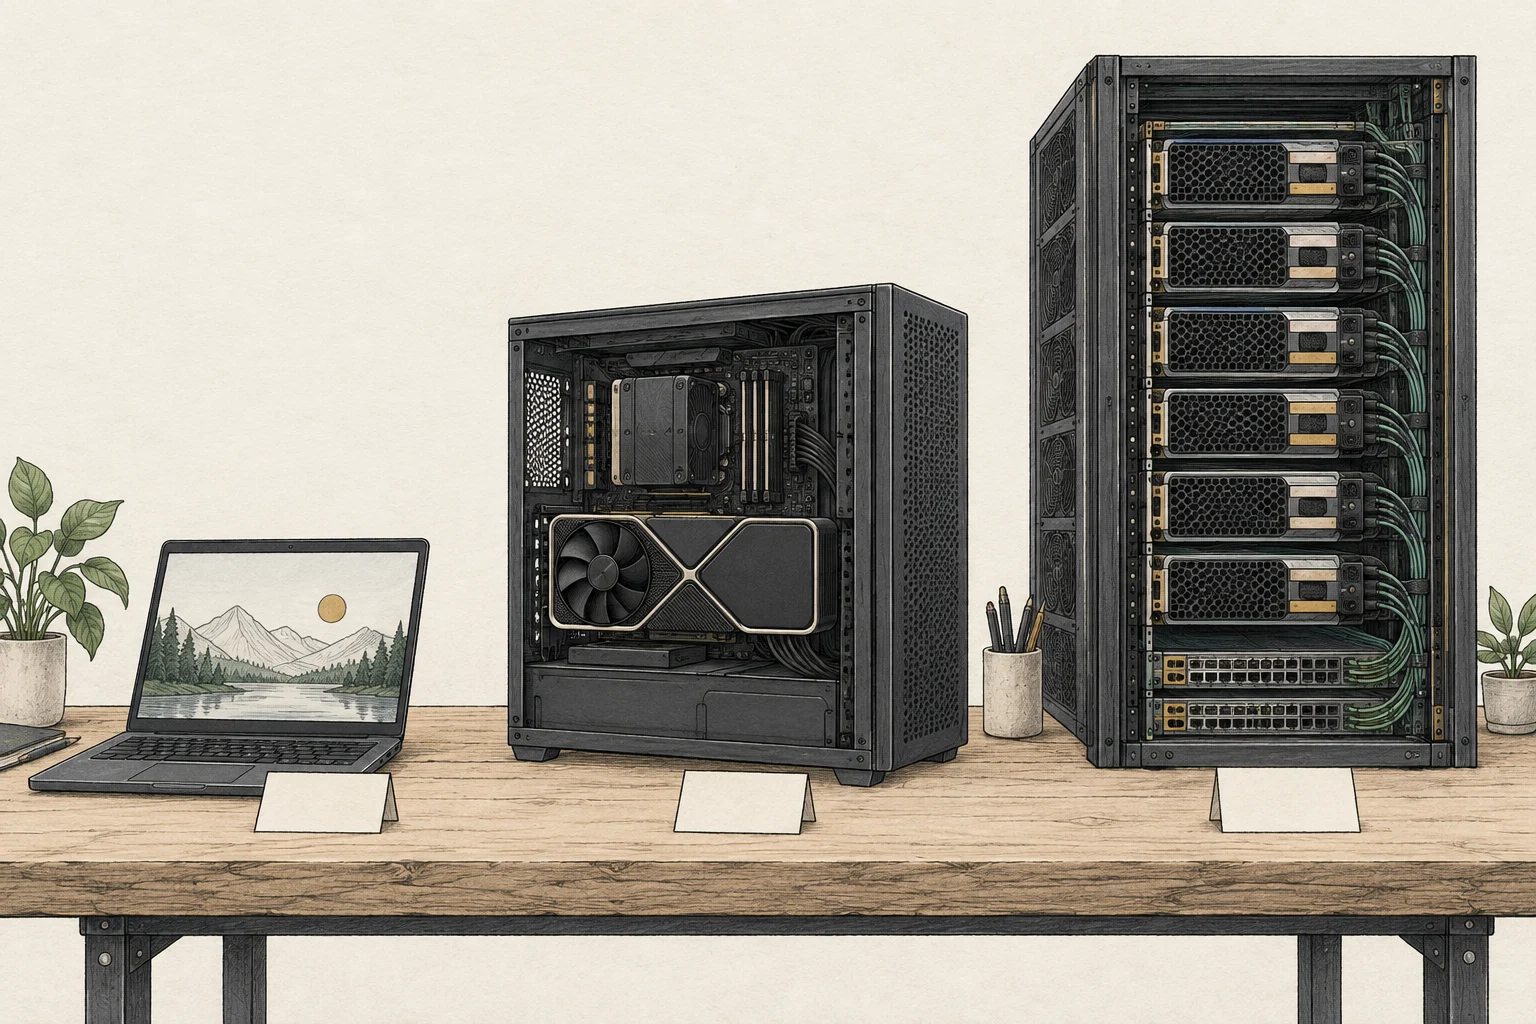
Check each repository with the same choices and inputs
Use the same ticket and action candidates across the projects. Convert each request to the project’s documented interface, then record its response keys and which choice each probability belongs to.
For CPU tests, record load time and per-query latency; for personal 4B GPU runs, record VRAM12 and batch limits; for servers, log concurrency and accelerator use. Do not combine measurements from different conditions into one ranking.
Choose trained projects by data coverage and error cost
kev adds LoRA13 and a small readout head to Qwen2.5-0.5B to handle a document and multiple questions in one sequence. qwen-rlcd trains Qwen3.5-0.8B for Choice, Score, and Noul decisions. These adapt more to decision structure than direct score-reading baselines, but performance can be limited by training and evaluation coverage.
Test whether results hold across phrasings such as 'charged twice' and 'seems to be a duplicate payment,' and whether confidence is useful for review. The baseline, small CPU API, and B200 server use different models and tasks, so do not rank them directly; measure accuracy, calibration, and latency on the same business data.
Validate open implementations in the real workflow
Even a good score on sample tickets may not cover long context, duplicate choices, or missing fields in production inputs. Keep a fixed test set containing those cases and record model revision and dependency versions.
For training-focused projects, inspect data provenance, licensing, and correction workflows. If a misclassification is costly, limit automation and keep human review as the default path.
Route an inquiry with a llama.cpp decision model
The /v1/systemone API in llama.cpp 0.6.0 can run Kev-4B, based on Qwen3.5-4B. Send an inquiry and candidate teams; the selected team is returned in answers.route.choice. This example uses the Q4_K_M file. Kev-4B model card
Prepare llama-server version 0.6.0 or later and run the first command. When the server reports that it is ready, send the second command from another terminal. Describing each team's responsibilities alongside its label makes the classification criteria clearer.
Inspect the selected value and each option's probabilities. If the connection fails, check /health first. For a 501 error, verify that a decision model is loaded; for a 400 error, check the state and questions input format. Before routing real inquiries automatically, test against human-labeled inquiries and set a threshold for sending uncertain cases to a person. Official API documentation
llama-server -hf ggml-org/Kev-4B-GGUF:Q4_K_M --host 127.0.0.1 --port 8080 --ctx-size 4096curl -sS http://127.0.0.1:8080/health
curl -sS http://127.0.0.1:8080/v1/systemone -H 'Content-Type: application/json' -d '{"state":"I was charged twice for my subscription.","questions":{"route":{"type":"choice","instructions":"Which team should handle this inquiry?","criteria":{"billing":"payments, charges and refunds","access":"login and account access","security":"suspicious activity and account protection"}}}}'Terminology notes
CPU — The central processor that runs the operating system and general-purpose instructions; in AI workloads it also handles tasks such as preprocessing and data movement.
Back to the textAPI — A defined interface that lets other code call a program’s functions.
Back to the textThroughput — The amount of work processed or generated over time. Comparisons need the unit, such as tokens per second or requests per second.
Back to the textRuntime — The software environment that provides facilities needed while a program runs. In local AI, it can also refer to a model execution engine.
Back to the textPrefill — The stage where an LLM reads the input prompt and computes representations for its tokens. Longer prompts contain more tokens to process.
Back to the textCUDA — A software platform for general-purpose computing on NVIDIA GPUs.
Back to the textMLX — Apple’s machine-learning framework, which runs models using memory shared by the CPU and GPU on Apple Silicon.
Back to the textPyTorch — A software framework for building and running AI models. Check the compatible PyTorch version and hardware support along with the model.
Back to the textGPU — A processor designed to handle many calculations in parallel. It performs model computations during AI inference.
Back to the textNVFP4 — A 4-bit floating-point data format defined by NVIDIA. Support depends on GPU generation, model, and software implementation.
Back to the textCheckpoint — A file containing saved model weights and related state. Versions or tasks in one model family may use different checkpoints.
Back to the textVRAM — Memory used by a graphics card’s GPU to store model weights and intermediate values.
Back to the textLoRA — A method that learns and applies small additional weights to adapt a base model. The adapter is used with the base model for purposes such as style adaptation or few-step generation.
Back to the text
Frequently asked questions
- What should you check first in this article?
- Qwen-based Jev-style projects take documents and choices and return classifications and candidate scores. SemIf targets 4B personal-machine experiments, Simple Jev demonstrates a 0.8B CPU API, and openjev-sglang focuses on 35B parallel server processing. Choose a starting point for your hardware and decision task.
- How much memory does it need?
- For CPU tests, record load time and per-query latency; for personal 4B GPU runs, record VRAM and batch limits; for servers, log concurrency and accelerator use. Do not combine measurements from different conditions into one ranking.
- Where can you check the conditions and sources?
- The `/v1/systemone` API in llama.cpp 0.6.0 can run Kev-4B, based on Qwen3.5-4B. Send an inquiry and candidate teams; the selected team is returned in `answers.route.choice`. This example uses the Q4_K_M file. [Kev-4B model card](https://huggingface.co/ggml-org/Kev-4B-GGUF)